Building Data Pipelines in Singdata without Code
Build secure, automated Data Pipelines in Singdata without coding. Drag-and-drop tools and AI features make data integration fast, easy, and scalable.
Master Spark SQL join optimization, Structured Streaming exactly-once guarantees, YARN OOM troubleshooting, and real-time CDC ingestion with Singdata Lakehouse.
Build secure, automated Data Pipelines in Singdata without coding. Drag-and-drop tools and AI features make data integration fast, easy, and scalable.
Performance Benchmarks for fully managed log query solutions: compare latency, throughput, concurrency, and scalability to choose the best platform.
Automated Data Replay enables self-healing data pipelines, ensuring fast recovery, data accuracy, and minimal manual intervention after failures.
Unified Batch & Stream streamlines backfill by unifying batch and streaming jobs, reducing errors, boosting reliability, and improving data quality.
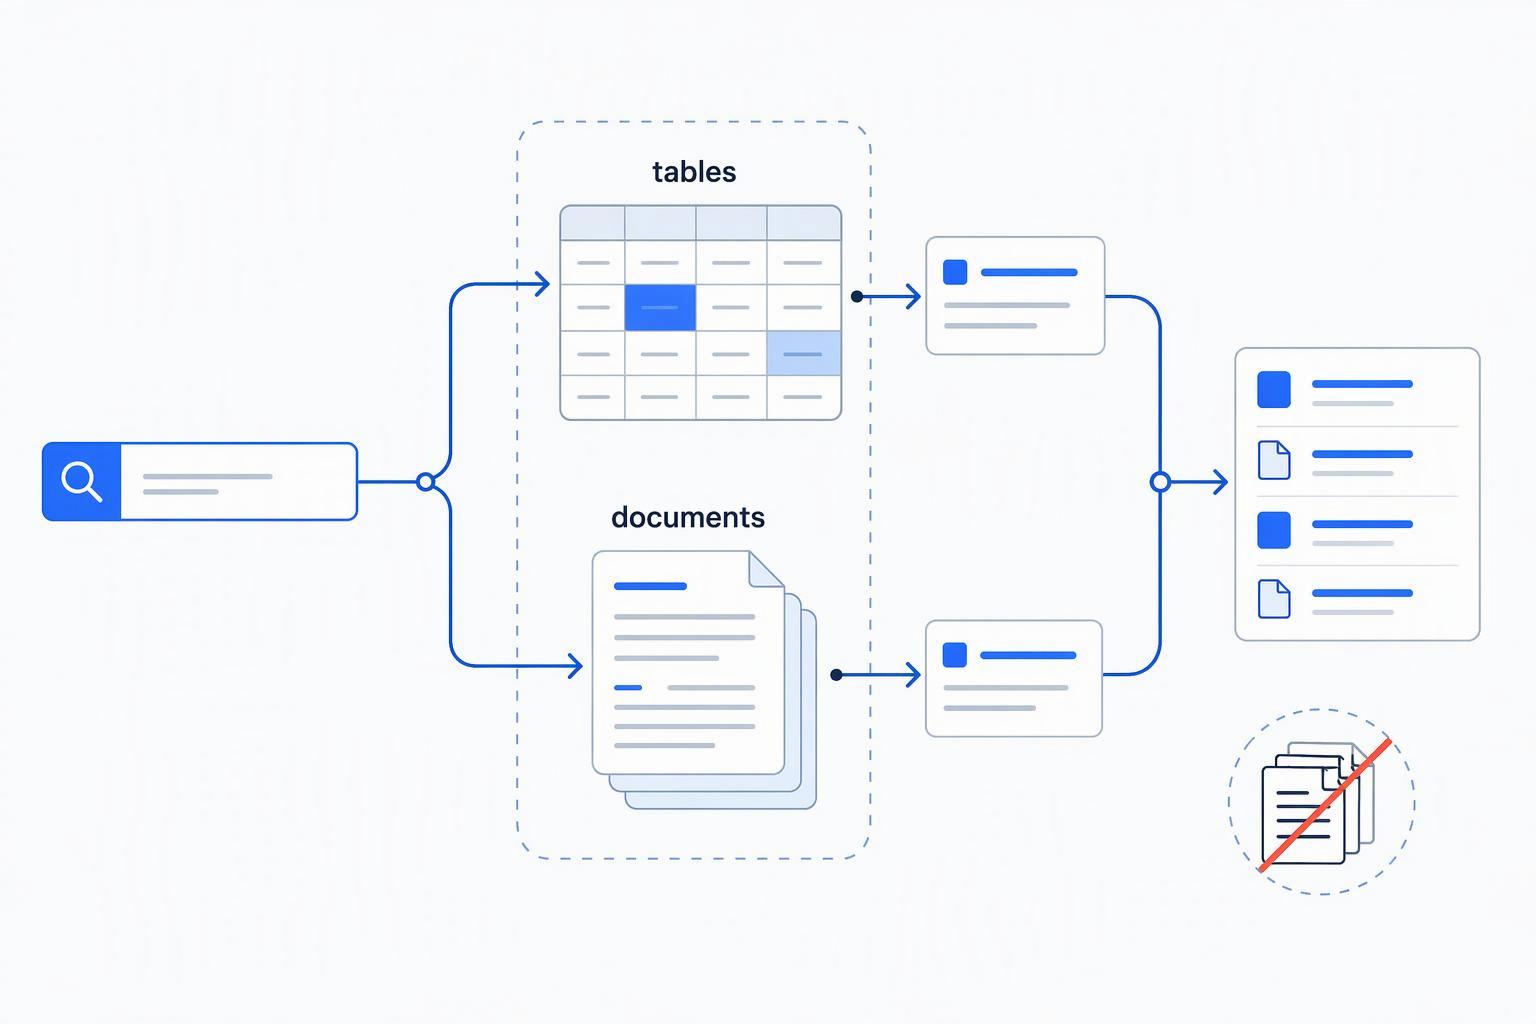
A practical guide to searching tables and documents across systems without bulk copying: zero-copy access, metadata and derived-index copies, federated query limits, open table format portability, storage-compute separation, compute contract risk, and residency constraints, with an acceptance checklist to test before you sign.
Get the latest reviews and insights in this category delivered to your inbox.
Learn More