
Why "One Metric, One Definition" Is the Only Analytics Rule That Scales
Why one governed definition per metric stops KPI drift, plus an ownership model and a six-point acceptance checklist you can apply this quarter.
A definition nobody enforces is documentation, not governance. That distinction is the first thing to test when you evaluate a metric program, because it separates a glossary that reads well from a system that returns the same number to every consumer. The stakes are measurable: in a Wakefield Research survey of 200 US data engineers, 68% of respondents were not fully confident their data was reliable enough for AI use cases (Monte Carlo / Wakefield Research, fielded 2024-04-24 to 2024-05-07). Trustworthy analytics starts with one governed definition per metric, owned, versioned and resolved in a single place. This article gives you the operating model and an acceptance checklist you can apply this quarter, and it connects the same principle to why AI projects need shared meaning before agents are allowed to answer business questions.
What "One Metric, One Definition" Actually Means
The rule means one approved meaning per metric, held independently of any single table, column or dashboard. ISO/IEC 11179-1:2023, the fourth edition of the metadata registry standard published in 2023-01, separates a concept's meaning from its representation, and its Part 4 rules require definitions to state essential meaning, stand alone, and exclude implementation detail (ISO/IEC 11179-1:2023, 2023). DAMA-DMBOK, the data management body of knowledge, supplies the accountability half: data governance is the exercise of authority, control and shared decision-making over data assets, and data stewardship is formal accountability for a definition's usage and quality (DAMA International, 2nd edition 2017). Official statistics reached the same conclusion earlier, and the UN Fundamental Principles of Official Statistics, endorsed by the General Assembly in resolution 68/261 in 2014, require agencies to present information on sources, methods and procedures according to scientific standards (UN Statistics Division, 2014). One limitation: the operating model below is a synthesis of published practice, and the illustrative scenario is inference, not a measured case.
Why Dashboards and Reports Disagree on the Same KPI
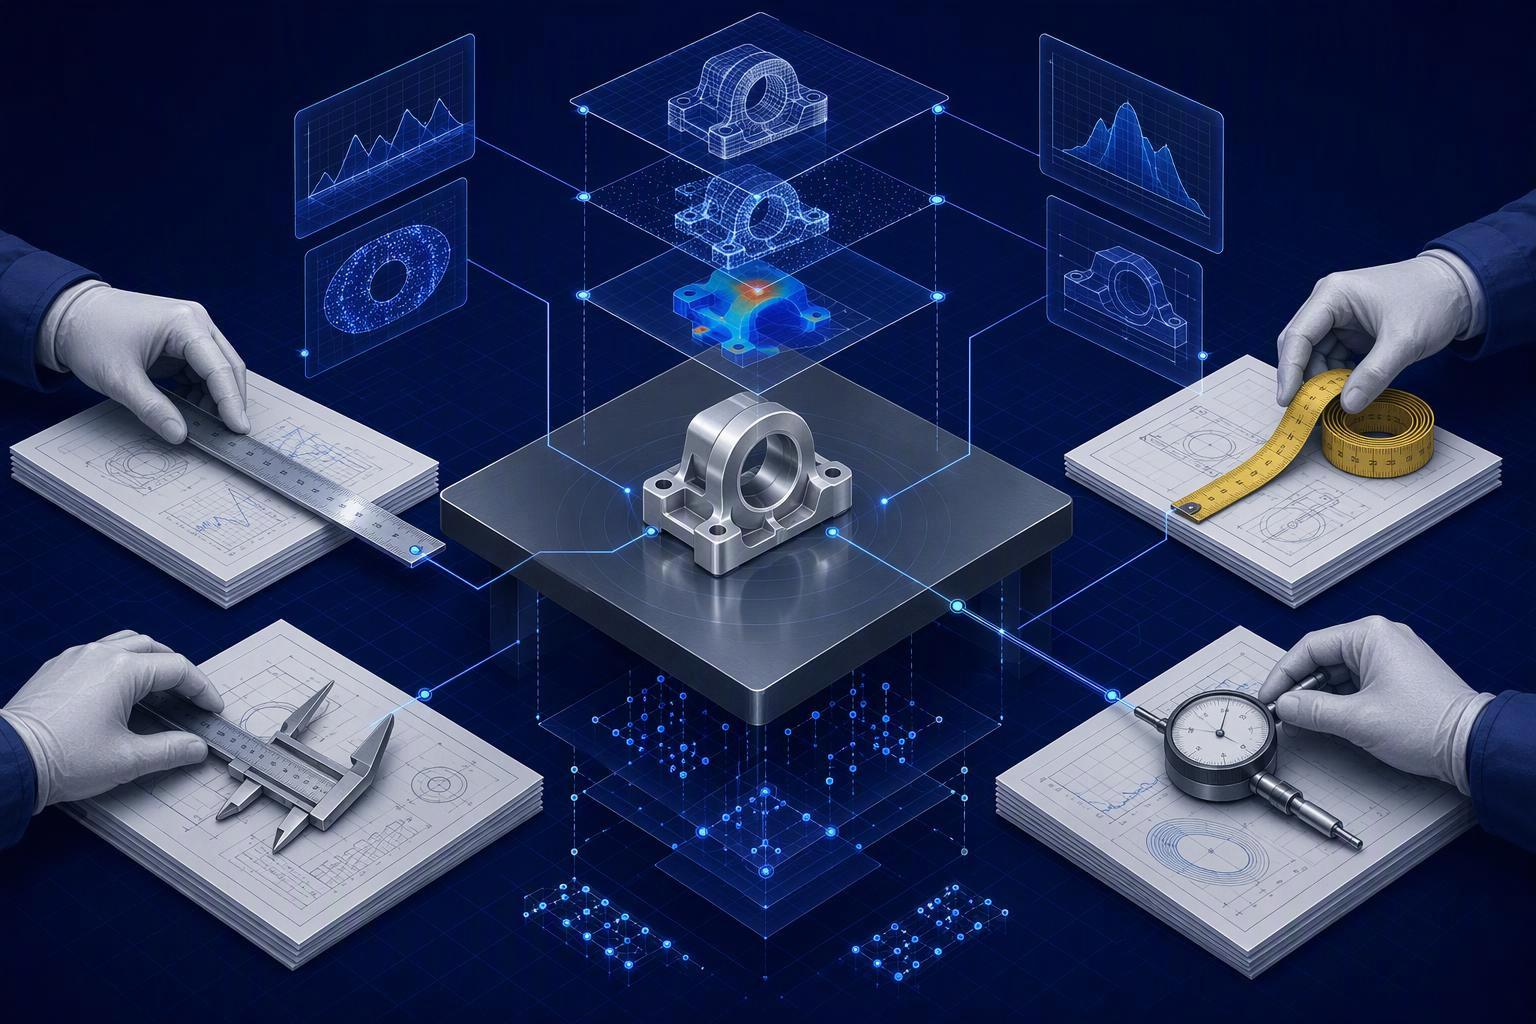
Disagreement is usually drift, not error, and drift has a small number of named causes. The same Wakefield survey found two-thirds of data leaders did not completely trust the data their AI applications were built on, while 91% said they were actively building those applications (Monte Carlo / Wakefield Research, 2024). No analyst survey located for this article quantifies how often organizations disagree on a KPI definition, so treat the failure mode qualitatively. The mechanism is documented: dbt's semantic models fix grain, entities and dimensions, so a metric cannot be regrouped differently per dashboard (dbt Developer Hub, 2026), and Looker's LookML documentation states that analysts "write SQL expressions once, in one place," with the SQL generator translating that model into queries (Google Cloud, docs current 2026). Typical drift: definition, source system, grain, date field, cutoff or timezone, filter, formula, refresh latency, and join key. A valid query can still answer the wrong question, which is the distinction behind SQL accuracy versus analytics accuracy.
What a Governed Metric Definition Must Contain
A governed definition is a record with required fields, and each missing field has a predictable failure mode. dbt's metric specification requires name and type (conversion, cumulative, derived, ratio or simple), plus type-specific parameters: agg for simple, expr and input_metrics for derived, numerator and denominator for ratio, input_metric for cumulative, and entity, calculation, base_metric and conversion_metric for conversion (dbt Developer Hub, docs current 2026). Optional fields carry governance weight: description, label, config (meta, group, tags, enabled) and filter, which the docs describe as a WHERE clause applied to dimensions, entities, time dimensions or other metrics. The semantic model underneath supplies the required agg_time_dimension, entities as join keys, and time or categorical dimensions (dbt Developer Hub, 2026). Looker's equivalent is dimensions and measures defined once in a view, with structure separated from content (Google Cloud, 2026). Drop the grain and two teams aggregate at different levels; drop the filter and one dashboard includes test orders; drop the label and the AI agent picks the wrong field. Consistent definitions are what make answers testable, as covered in how a semantic layer makes AI answers testable.
Field | Failure mode when missing |
|---|---|
Name and type | Duplicate or ambiguous metrics; consumers pick the wrong one |
Aggregation ( | Sum versus average disagreement on the same column |
Numerator and denominator | Ratio metrics drift; rates stop reconciling |
Time dimension and grain | Different rollups; month-to-date versus calendar month |
Filter | Test, internal or cancelled records leak into published numbers |
Label and description | Ambiguous field selection, especially by AI agents |
Who Owns a Metric, and How Does It Change Safely
Ownership is deliberately split, and dbt Labs' guidance on semantic layer ownership says there is no universal answer but recommends a hybrid: business and domain teams own the definitions because they understand the business meaning, while data and analytics teams own deployment, credentials, integrations, access controls and performance (dbt Labs, edited 2025-11-20). The reason is technical: a simple metric can generate hundreds of lines of optimized SQL. Catalog tooling carries the accountability record. Collibra's data catalog organizes metadata with definitions, owners, classifications and policies, and its stated function is to certify trustworthy data and surface relevant metrics, with data owners assigning responsibilities and tracking usage (Collibra, undated product page). Versioning is the part most teams skip: a version stamp, an effective date and a change notification to downstream consumers. Without them, a definition change silently rewrites history for every dashboard, and the next quarter's comparison is invalid.
How Is the Definition Enforced, Not Just Documented
Enforcement is a compile step: the consumer asks for a metric, and one engine generates the SQL from the approved definition. MetricFlow compiles the query, dynamically renders joins for entities, and the docs state it "intelligently avoids fan-out and chasm joins," with agg described as one of the elements of achieving metric consistency (dbt Developer Hub, 2026). Looker's SQL generator translates LookML into SQL so business users query without writing either (Google Cloud, 2026). Cube's definition of a semantic layer describes the governed layer between the warehouse and consuming tools, compiling requests using defined join paths and metric logic, "not whatever the tool guessed" (Cube Dev, 2026-06-14). Public-sector evidence shows what auditable enforcement looks like: GAO-25-107469 reports that of the 70 federal agencies reporting procurement data to FPDS for fiscal year 2023, 36, or 51%, confirmed completion of data quality reports, and it names the 34 that did not (GAO, published 2025-09-25). That is compliance in one reporting domain, not evidence about enterprise AI pipelines. The cost figures are dated and scoped: Gartner's estimate of $12.9 million a year per organization is reported by Forbes (Forbes Communications Council, 2025-10-22), while the $3.1 trillion US figure is a 2016 IBM estimate relayed by Thomas Redman in Harvard Business Review with unpublished methodology (HBR, 2016-09-22). Different units of analysis, both dated. The enterprise semantic layer explained in more depth covers how these compile layers are architected (Singdata).
How Do I Verify a Definition Is Actually Enforced
Verification is a reproducibility test, not a documentation review. Take one metric, ask two people in different teams to produce it independently, and compare the numbers, the grain, the filter and the time window. If the governed layer is doing the work, both requests resolve through the same compile step and return identical results, which is the same-numbers-across-consumers property Cube describes for dashboards, embedded apps, spreadsheets and agents (Cube Dev, 2026-06-14). A neutral example: a revenue metric with numerator, denominator and time window fixed in the governed layer resolves the same way whether it is requested from a dashboard, an embedded application or an agent. Singdata supports governed metric consumption across lakehouse and agent workloads, which is one option among several if you are evaluating platforms. The acceptance checklist:
Lineage: every metric traces to its source tables and the semantic model that defines its grain.
Tests: automated checks run on the metric, not only on the upstream table.
Freshness: the metric record states its refresh cadence and last successful load.
Audit trail: changes are versioned with an author, an effective date and a reason.
Reconciliation controls: published numbers reconcile to a finance or operational baseline.
Reproducibility: two independent requesters get the same result without manual adjustment.
Why This Matters for AI and Data Agents
An agent has no institutional memory, so it inherits whatever the semantic model says and nothing else. Looker's guidance for conversational analytics states that the tool uses the semantic model, data values and agent configuration as its source of truth, and that "the effectiveness of Conversational Analytics is directly tied to the quality and clarity of these inputs" (Google Cloud, docs current 2026). The documented failure mode is field selection: fields that lack clear labels, have ambiguous definitions, or share similar names across views lead to incorrect choices, and dashboard-level custom fields or table calculations make business logic inaccessible to the agent. Cube's equivalent warning is that raw-schema access leaves the tool guessing at join paths and metric logic (Cube Dev, 2026-06-14). Atlan's comparison of semantic layer, metrics layer and data catalog places the semantic layer as the AI-ready option, with a metrics layer as a narrower form of it (Atlan, updated 2026-07-30). The practical consequence: metric resolution is now an AI reliability question, which is why text-to-metric resolution determines whether an agent's answer is defensible.
Frequently Asked Questions
What does "one metric, one definition" mean in practice?
It means a single approved meaning per metric, held in one governed place and resolved by every consumer from that record. The definition covers grain, numerator and denominator, filter, time dimension and version, not just a business description. If two teams can produce the metric from different logic, you have two definitions.
Why do two dashboards show different numbers for the same KPI?
Usually because of drift in one of a few places: grain, source system, date field, timezone or cutoff, filter, formula, refresh latency or join key. Each dashboard may be technically correct while answering a slightly different question. Fixing the definition in a governed layer removes the divergence at the source rather than reconciling it after the fact.
Who should own a metric definition?
Business and domain teams should own the definition, because they hold the business meaning, while data and analytics teams own the infrastructure that implements it. dbt Labs' guidance on semantic layer ownership recommends exactly this hybrid split, noting that implementing metrics is technically complex (dbt Labs, edited 2025-11-20). Catalog tools record the owner, the certification status and the change history.
How do we know a definition is enforced rather than just written?
Run a reproducibility test: have two people in different teams produce the metric independently and compare the number, grain, filter and window. If both requests compile through the same governed logic, the results match without manual adjustment. Documentation alone cannot pass this test, because nothing prevents a consumer from writing its own SQL.
Does a governed metric layer actually improve AI accuracy?
The platform documentation says the agent's output quality is tied to the clarity of the semantic model it reads, not to the model's raw capability. Looker's guidance states that ambiguous or missing labels and descriptions cause incorrect field selection (Google Cloud, 2026). No source located for this article reports a measured accuracy improvement from adopting a semantic layer, so treat the benefit as architectural.
We already documented definitions in a wiki. What are we missing?
A wiki records meaning but does not enforce it, so each consumer still writes its own query logic. Enforcement requires the definition to be compiled into the query, which is what MetricFlow and Looker's SQL generator do (dbt Developer Hub, 2026). Keep the wiki as context and move the calculation into the governed layer.
How many metrics should we govern first?
Start with the metrics that appear in executive reporting and AI answers, not the full catalog. Gartner's guidance on finance KPIs states there should be no more than five KPIs per driver (Gartner, updated 2025-08-07). A smaller governed set that every consumer uses beats a large glossary nobody queries.
Conclusion
The rule scales because it moves the decision from each consumer to one record: one approved meaning per metric, owned by the business, implemented by data teams, versioned with an effective date, and compiled into every query. The evidence for the failure mode is consistent across independent sources, from the 68% of surveyed data engineers who were not fully confident their data was AI-reliable (Monte Carlo / Wakefield Research, 2024) to the 51% of federal agencies that could confirm completion of their procurement data quality reports (GAO, 2025-09-25). The evidence stops short of a measured accuracy gain from adopting a semantic layer, so the case rests on mechanism and auditability rather than a benchmark. Apply the checklist to one executive metric this quarter: confirm lineage, tests, freshness, audit trail, reconciliation controls and reproducibility. If any item fails, you have documentation, not governance. To see how governed metrics are consumed across dashboards, embedded applications and agents, talk to an expert.