
Natural Language Analytics Tools with Permission Controls: A Buyer's Comparison
Compare how Snowflake Cortex Analyst, Databricks Genie, Looker, ThoughtSpot, Power BI Copilot, Qlik Answers, Tableau Pulse and Amazon Quick enforce row-level, column-level and identity-based permissions for natural language queries, with a test procedure and acceptance checklist.
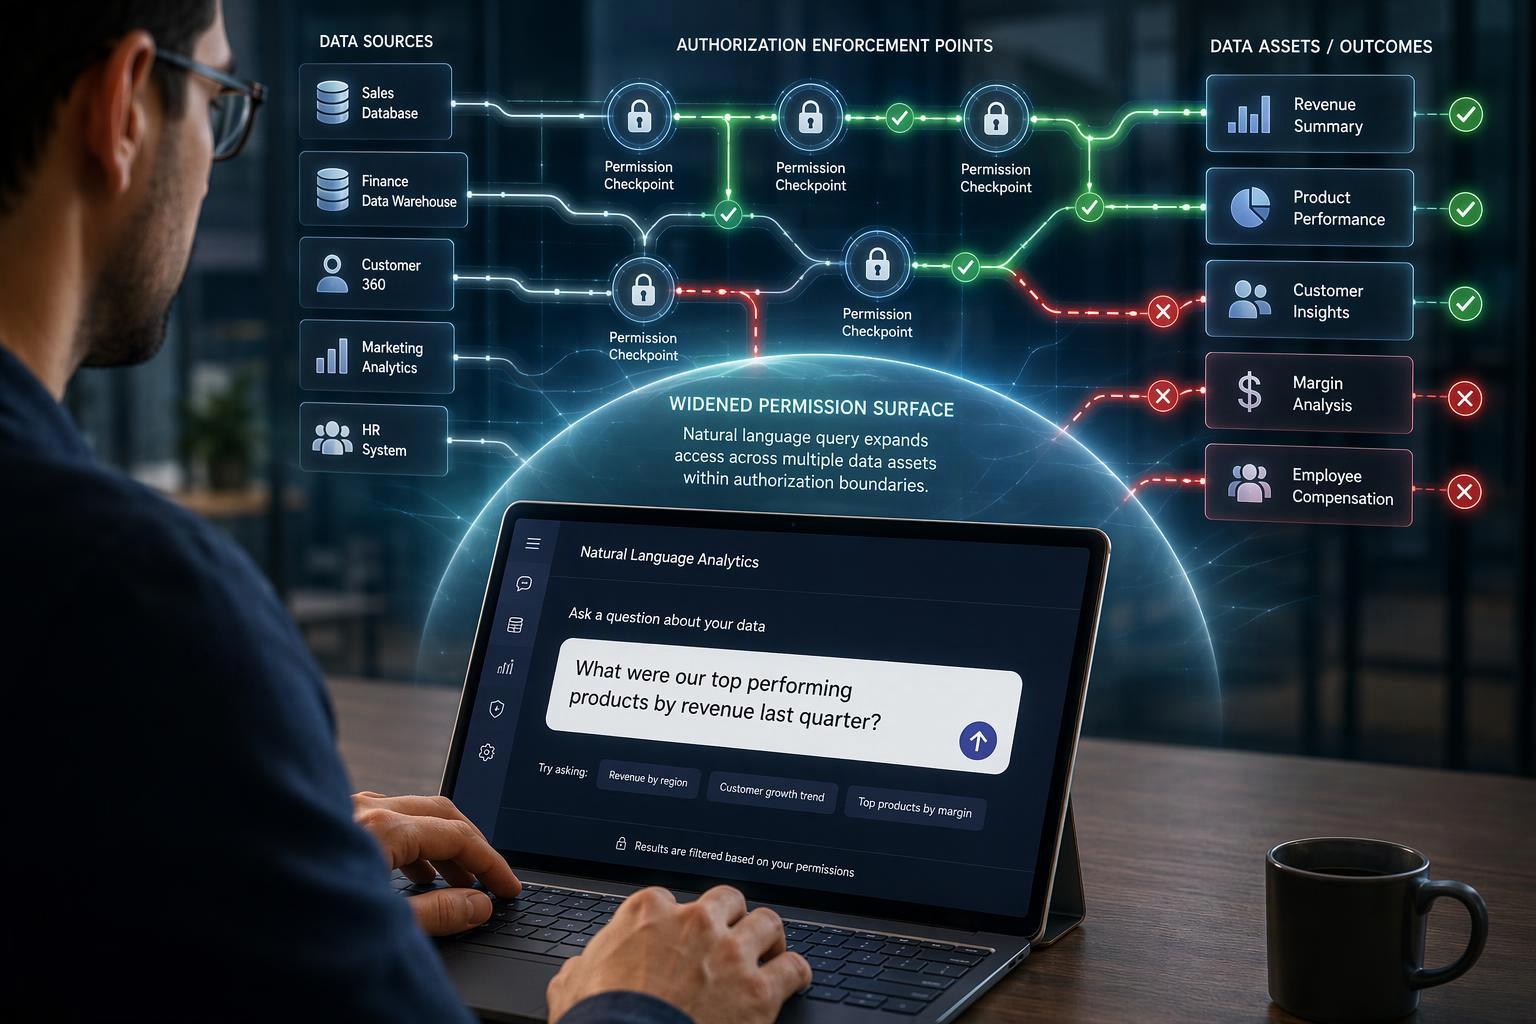
Most buyers evaluating natural language analytics ask the wrong question. They ask which tools list role-based access control, row-level security, or column masking on their feature pages. Almost all of them do. The question that decides your exposure is narrower and harder: when a user types a question instead of opening a dashboard, where is authorization actually enforced, and as whose identity does the generated query run?
That distinction matters because natural language widens the permission surface. A generated SQL statement can reach tables a curated dashboard never touched. An agent can chain several queries in one turn. A service account used for indexing or compute can flatten per-user identity into a single privileged principal. A shared semantic layer can grant access to a view without requiring access to the tables beneath it. None of these are hypothetical failure modes; each one is documented behavior in at least one mainstream product below.
This comparison is therefore organized by enforcement layer and testable behavior rather than by vendor marketing. It covers Snowflake Cortex Analyst and Snowflake Copilot, Databricks Genie, Looker Conversational Analytics, ThoughtSpot, Power BI Copilot, Qlik Answers, Tableau Pulse, and Amazon Quick, then gives you a test procedure and an acceptance checklist you can run before signing. Every product claim is attributed to the vendor's own documentation, and where the documentation is silent, this article says so rather than filling the gap.
Comparison at a Glance
The matrix below maps each tool to the criteria developed in the next section. "Documented" means the vendor states the behavior in first-party documentation; "not documented" means the retrieved pages do not address it, which is not evidence that the control is absent.
Tool | Primary enforcement layer | Identity model for generated queries | Row/column controls | Documented caveat worth testing |
|---|---|---|---|---|
Snowflake Cortex Analyst | Warehouse (Snowflake RBAC) | User's role; API calls require an authorization token | Row access policies and masking policies on base tables propagate to semantic views | Semantic views use owner's rights, so policies must sit on base tables |
Snowflake Copilot | Warehouse (Snowflake RBAC) | Signed-in user | Inherited from Snowflake RBAC and policies | Suggestions are limited to datasets the user can access |
Databricks Genie | Warehouse (Unity Catalog) | Data access as end user; compute credentials from agent author | Unity Catalog row filters, column masks, ABAC policies | Compute runs under author-embedded credentials; end users need no warehouse permissions |
Looker Conversational Analytics | Semantic layer (LookML) | User's Looker permissions and user attributes | Access filters, access grants, model sets | Data agents require underlying model permissions even when the agent is shared |
ThoughtSpot | Semantic layer plus database | User or group | Table-level RLS, strict RLS by default | Bypass RLS on a Model does not cover queries on Views built on those tables |
Power BI Copilot | Semantic model (RLS/OLS) | Signed-in user's existing permissions | RLS and OLS continue to apply | RLS restricts only Viewer-role users, not Admin, Member, or Contributor |
Qlik Answers | Application (Section Access) | User's Section Access permissions at query time | Section Access row and column reduction | Index scope and query-time rules are independent layers |
Tableau Pulse | Data source permissions | User's data source access | RLS on the data source is respected | Metrics are not governed by content-based permissions |
Amazon Quick | Dataset RLS (Enterprise Edition) | User, group, or session tag | User/group-based and tag-based rules | Dataset owners still see all data; readers see restricted data |
The pattern is that no two tools enforce at the same layer, and the layer determines what a test can prove. A warehouse-native tool inherits whatever policy you already maintain in the warehouse. A semantic-layer tool enforces what you define in its modeling language. An application-layer tool enforces its own rules, which may or may not align with the warehouse beneath it.
Evaluation Criteria
Five criteria separate a genuinely governed natural language deployment from one that merely has a permissions tab. They are ordered from the most structural to the most operational.
Where Authorization Is Enforced
Authorization in analytics generally lives at one of three layers. The warehouse layer covers role-based access control, row access policies, and column masks applied to tables and views. The semantic layer covers modeling constructs such as LookML access filters, Power BI RLS and object-level security, and ThoughtSpot RLS. The application layer covers tool-side filters, sharing permissions, and content access.
The strongest posture enforces at the lowest layer the generated query actually reaches. If a natural language tool writes SQL against warehouse tables, warehouse policy is the control that survives prompt variation, because it applies to every query regardless of how the question was phrased. If the tool composes queries through a semantic model, the semantic layer is the effective control, and warehouse grants may be bypassed by design. If the tool answers from its own index or cache, only application-layer rules apply, and everything depends on how faithfully that index was filtered.
Natural language tools vary in which layer they hit, and some hit more than one. Looker, for example, does not let the agent write the whole SQL query; it determines fields, filters, sorts, and limits, and Looker composes and executes the query through the underlying LookML model, so the join logic, filtering, aggregation, and data permissions defined in the model apply. Snowflake Cortex Analyst, by contrast, generates SQL that executes under Snowflake RBAC. Those are different guarantees, and the buyer should know which one they are getting.
Identity Propagation and Service Accounts
The single most consequential question is whether the tool evaluates access as the end user or as some other principal. A tool that runs generated queries under an author's or indexing account can return data the asking user could never retrieve directly, even when the dashboard layer looks locked down.
Databricks Genie documents the split explicitly. The generated SQL runs on the SQL warehouse using compute credentials embedded by the agent author, so end users do not need direct warehouse permissions. Data access, however, is evaluated by Unity Catalog as the end user's own identity, not the author's, and each query is attributed to the end user in query history and the agent's monitoring page. That is a defensible design: compute is delegated, data access is not.
Qlik Answers documents a comparable separation from the other direction. If the indexing user has full access, the index captures all application data, but Section Access rules are still enforced at query time. The two layers are independent, so each user only receives results they are permitted to see. The lesson for buyers is that an indexing account with broad scope is not automatically a leak, provided a second, user-scoped enforcement layer exists at query time. Ask specifically whether that second layer exists.
Row-Level and Column-Level Controls
The question here is not whether a tool supports row filters, but whether those filters propagate to the natural language surface. Documented propagation is the only reliable signal.
Snowflake states that row access policies and masking policies cannot be set directly on semantic view attributes, but if they are set on underlying tables and columns, they propagate to semantic views and are enforced. Power BI states that RLS and OLS on semantic models continue to apply to Copilot. Tableau states that the data users see when viewing a Pulse metric respects row-level security applied to the data source. ThoughtSpot defines RLS at the table level, so searches, Answers, Models, and Liveboards that rely on a table's data fall under its RLS rules.
Each of these is a documented propagation claim, and each has boundaries. The Power BI boundary is role-based, covered below. The ThoughtSpot boundary involves Models and Views, also covered below. The Snowflake boundary is that the policy must exist on the base table, because the semantic view itself will not carry it.
Semantic-Layer Owner's Rights and Bypass Risk
Snowflake semantic views use owner's rights, meaning a user with access to a semantic view does not require separate access to its underlying tables. To query a semantic view, a user needs only the SELECT privilege on the semantic view itself.
This is a genuine security benefit: you can expose a curated analytical surface without granting table-level access, and the underlying policies still propagate. It also creates an obligation. Because the semantic view does not require table grants, the only thing standing between a user and unrestricted rows is the policy on the base table. If your team builds semantic views over tables that lack row access policies, owner's rights becomes a bypass rather than a control. The same logic applies to any semantic layer that grants access to a view without requiring access to what it reads.
Auditability and Query Attribution
If a user receives data they should not have seen, you need to reconstruct what happened: which user, which question, which generated query, which rows. Tools differ in what they retain.
Databricks attributes each Genie query to the end user in query history and the agent's monitoring page, and its audit log reference includes Genie-specific parameters such as the Genie space, conversation, and message identifiers for API calls. Snowflake's ACCESS_HISTORY view supports read-operation analysis, including queries that identify which users accessed a given table object over a time window. Where a vendor's documentation does not describe per-user attribution for its natural language surface, treat that as an open item to confirm in a trial rather than assuming either capability or absence.
Tool-by-Tool: Where Each Enforces Permissions
The subsections below apply the same four questions to each tool: enforcement layer, identity model, documented row and column controls, and documented caveats.
Snowflake Cortex Analyst and Copilot
Cortex Analyst generates SQL that adheres to Snowflake's role-based access control policies, so generated and executed queries are subject to the same grants as any other SQL in the account. Requests to the Cortex Analyst API must include an authorization token, and access to the underlying semantic model stage can be restricted by revoking the PUBLIC role and granting specific roles instead. Because semantic views use owner's rights, row access and masking policies must be defined on the underlying tables and columns, from which they propagate and are enforced.
Snowflake Copilot states that it fully respects RBAC and provides suggestions based only on the datasets the user can access. Access to Copilot features is itself granted through roles. For a Snowflake-standardized organization, this is the cleanest identity story in the comparison: the natural language surface adds a generation step but does not add a new authorization model.
Databricks Genie
Genie's documented model is the clearest example of delegated compute with preserved data identity. Compute credentials are embedded by the agent author; data access is evaluated by Unity Catalog as the end user. Unity Catalog provides two mechanisms for row and column control: dynamic views, which wrap base tables in SQL that filters or masks and are typically gated by group-membership functions, and ABAC policies, which Databricks recommends when consistent filtering and masking is needed across many tables because they attach at catalog or schema level, apply automatically based on governed tags, and cannot be overridden by table owners.
Databricks also documents that when the query engine must choose between optimization and protecting against information leakage from filtered or masked values, it always makes the secure choice, which can affect performance. That is a useful disclosure: security can cost query speed, and expressions that can throw errors, such as ANSI division, prevent pushdown because the error itself could reveal information about pre-filter values.
Google Looker Conversational Analytics
Looker's approach is semantic-layer-native. Conversational Analytics does not query the database directly; it determines which fields, filters, sorts, and limits to use, and Looker composes and executes the query through the LookML model, applying join logic, filtering, aggregation, and the data permissions defined in the model, including access grants and user attributes.
The documented distinctions between surfaces matter for access. Explore conversations are typically limited to one user and are not shareable. Explore data agents can be shared by granting content access, but they require access_data and other permissions on the models underlying the Explores, and sharing the agent does not grant access to those Explores. Dashboard agents are managed strictly through dashboard-level permissions and model permissions, and inherit the dashboard's sharing model. A buyer who assumes that sharing an agent shares its data is making an expensive assumption.
ThoughtSpot
ThoughtSpot defines RLS at the table level and at group or user level, and states that searches, Answers, Models, and Liveboards relying on a table's data fall under its RLS rules. Strict RLS is the default on clusters, ensuring that a defined rule is always included in any query to the database, whether that query originates from a search or from a filter widget.
Two documented caveats deserve attention. First, when Bypass RLS is checked on a Model, it applies to queries involving tables but not to queries on Views based on those tables. Second, ThoughtSpot's documentation notes that not all RLS rules on underlying tables are applied when a user queries a Model, and that strict application, which takes into account RLS rules from all underlying tables, is the recommended configuration. The same documentation also warns that search indexes are built per RLS rule, and that passthrough security may expose search suggestions a user should not see, in which case indexing should be turned off for sensitive columns.
Microsoft Power BI Copilot
Copilot in Power BI uses the existing permissions of the signed-in user and can only access content that user is authorized to view; RLS and OLS on semantic models continue to apply. A Fabric administrator must enable Copilot, and the setting is off by default. Users with write permissions on a semantic model can also control whether read-only users can reach the model through Copilot experiences.
The critical caveat is documented plainly: RLS only restricts data access for users with Viewer permissions and does not apply to workspace Admin, Member, or Contributor roles. In practice, this means your Copilot exposure is bounded by workspace role hygiene. If business users who ask natural language questions are workspace Contributors, RLS is not protecting them, or the data from them.
Qlik Answers
Qlik Answers supports applications using Section Access and respects their rules. When accessing applications, Qlik Answers uses the permissions of the user and can only access content from a Section Access application the user has permission to access. The documentation states directly that users cannot expand their visibility through natural language questions in Qlik Answers, and that for Section Access applications, regardless of the indexing user, the data provided to end users is still controlled by the Section Access limitation.
Section Access itself works through a security table in the load script, where reduction fields with matching names in the access and application sections hide rows and columns from users after login. This is a mature, script-based model familiar to organizations with a QlikView heritage, and its strength is that the rule set is explicit and version-controlled with the application.
Tableau Pulse
Tableau documents a specific limitation for Pulse: metrics are not part of the project content hierarchy and are not governed by content-based permissions, so you cannot deny a user the ability to see an individual metric. Visibility is instead controlled by permissions on the published data source, and the data users see when viewing a metric respects row-level security applied to that data source.
For organizations with Data Management enabled, Tableau also supports row-level security through data policies on virtual connections, which centralizes RLS for each connection across all content that uses it. Tableau's own comparison of RLS options notes that manual and dynamic user filters must be replicated in every workbook and require secured permissions to prevent users from seeing unfiltered data, while data policies are centralized and low-maintenance but require the Data Management license.
Amazon Quick
In the Enterprise edition of Amazon Quick, you can configure row-level security on a dataset before or after sharing it. Rules can be user-based, group-based, tag-based, or a combination. The documented distinction is important: when you share a dataset with RLS with dataset owners, they can still see all the data, while readers see only the data permitted by the rules. For embedded dashboards serving unregistered users, tag-based rules filter data using session tags passed at embed time.
The practical implication is that dataset ownership is a privileged role in Quick. Anyone who owns the dataset sees everything, so ownership should be treated as a data-access grant, not merely an administrative convenience.
Why Natural Language Widens the Permission Surface
The documented behaviors above share a common structure, and understanding it explains why natural language changes the risk profile rather than merely changing the interface.
Generated SQL reaches further than a dashboard. A dashboard is a curated set of queries against a known set of tables. A text-to-SQL system can construct a query against any table the semantic model or the user's grants make reachable. Snowflake's documentation notes that semantic model stages may require SELECT access on all tables referenced in all semantic models on that stage, which is a broad grant by design. The blast radius of a question is therefore defined by the model's scope, not by the report's scope.
Agents compose multiple queries. Databricks documents an agent mode that breaks complex questions into sub-tasks, runs multiple SQL queries, and iterates until it has enough evidence. Each query in that chain is an opportunity for a different table, a different join, or a different filter to be involved. Authorization must hold at every step, which is why enforcement at the data layer rather than the interface layer is the more durable design.
Service accounts flatten identity. Where compute runs under author-embedded credentials, as Genie documents, the warehouse sees the author, not the asker. The only thing preserving per-user visibility is a second enforcement layer that evaluates the end user's identity. Qlik Answers shows the same pattern from the indexing side: a full-access indexing user captures all data, and Section Access must do the work at query time.
Caches and indexes can leak across users. ThoughtSpot documents that search suggestions come from an index rather than a database query, and that passthrough security may surface suggestions a user should not see. Power BI documents a Retry button that empties the Copilot cache to get a fresh result. Any surface that reuses prior computation needs a documented answer to the question of whose permissions the cached result was computed under.
Row limits are not authorization. A tool that returns the top 100 rows has not enforced access control; it has bounded output size. The distinction matters in procurement because result limits are sometimes presented alongside permission features, and they answer a different question.
None of this argues against natural language analytics. It argues for locating the control where the query actually lands, and for testing that location rather than the interface.
A Buyer's Test Procedure
This procedure is designed to be run in a trial environment with a test user before signing. It takes an afternoon and produces evidence you can put in front of risk and procurement.
Create a restricted test user. Give the user a role, group, or Section Access entry that should see a strict subset of rows, and no administrative workspace role. For Power BI specifically, confirm the user is a Viewer, because RLS does not apply to Admin, Member, or Contributor roles.
Ask questions whose correct answer is filtered. Prepare three or four questions where you know the full-population answer and the restricted answer. A response matching the full population is a finding, not a rounding error.
Inspect the generated SQL or composed query. Where the tool exposes generated SQL, read it: check which tables were referenced and whether a filter predicate appears. Where the tool composes through a semantic layer, inspect the resulting query or the tool's query log to confirm the model's filters were applied.
Check attribution in query history and audit logs. Confirm the query is recorded against the test user, not the agent author or an indexing account. In Databricks, check query history and the agent monitoring page; in Snowflake, query ACCESS_HISTORY for the accessed table and confirm the user name.
Attempt to elicit restricted data through the prompt. Ask directly for rows the user should not see, ask for totals that would only be computable from restricted rows, and ask the tool to ignore filters. Document the responses verbatim.
Test the missing-grant scenario. Remove the test user's access to an underlying table while leaving access to the semantic view or agent. In Snowflake, this tests owner's rights behavior directly. In Looker, test whether a shared data agent still requires model permissions.
Test the shared-content scenario. Share an agent, dashboard agent, or dataset with the test user and confirm that sharing did not widen data access. Looker documents that sharing an agent does not grant access to the underlying Explores; verify the equivalent in your environment.
Re-run the suite after any configuration change. Permission models interact, and a change to a workspace role, a semantic model setting, or an indexing configuration can alter the result.
Demand these artifacts from the vendor: sample generated SQL for a representative question set, resolver or query logs showing the composed query, an audit trail export covering the test user's activity, and a documentation link for each permission claim made in the sales cycle. A vendor who cannot produce the documentation link is asking you to accept an undocumented assurance.
Interpreting Vendor Permission Claims
Two words should anchor your procurement conversations: documented and verified. Documented means the vendor states the behavior in first-party documentation, which is the standard this article applies. Verified means you reproduced it in your own environment with your own users and data. Only the second is evidence about your deployment.
Three misreadings are common and expensive.
First, a category table is not proof for a specific tool. A comparison matrix showing that a product family supports row-level security does not establish that a particular natural language surface enforces it, or that it enforces it for the roles your users hold. The Power BI RLS limitation for non-Viewer roles is exactly the kind of boundary a category table omits.
Second, a sibling product's behavior is not proof. Snowflake Copilot and Cortex Analyst both respect RBAC, but they are different surfaces with different documentation, and the same is true across every vendor's portfolio. Ask for the page that covers the specific feature you are buying.
Third, a missing document is not evidence that a control does not exist. Vendors document unevenly, and an absent page may reflect documentation debt rather than a security gap. The correct response to silence is a scoped question and a test, not a rejection and not an assumption of safety.
Useful procurement language: "Please provide the first-party documentation page that states how generated queries are authorized for this feature, and confirm whether data access is evaluated as the end user's identity or a service account." And: "We will verify row-level filtering with a restricted test user during the trial; please confirm the configuration required to support that test." Both questions are answerable, and both produce a record.
Who Should Choose Which
The honest answer to "which tool should we choose" is that it depends on where your authoritative identity and policy store already lives. A natural language layer that duplicates your policy store creates a second thing to maintain and a second thing to get wrong.
Warehouse-native teams standardized on Snowflake should start with Cortex Analyst and Copilot, because the authorization model is the one they already operate, and row access and masking policies propagate from base tables. The work is ensuring those policies exist on the tables beneath every semantic view.
Teams standardized on Databricks should start with Genie, because Unity Catalog evaluates data access as the end user and ABAC policies centralize filtering and masking across many tables. The work is confirming that agent authors' embedded compute credentials do not exceed the data scope you intend, and that ABAC policies are in place before agents are shared broadly.
Semantic-layer-centric organizations should weight Looker and Power BI. Looker suits teams that already invest in LookML, because Conversational Analytics composes through the model and inherits its access filters, access grants, and user attributes. Power BI suits Microsoft-standardized organizations, provided workspace role hygiene is tight enough that RLS actually applies to the users asking questions.
Embedded and anonymous scenarios point toward Amazon Quick, where tag-based rules filter data for unregistered users at embed time, with the caveat that dataset owners see everything. Organizations with a QlikView or Qlik Sense heritage and script-based Section Access should look at Qlik Answers, whose documentation is unusually direct that natural language cannot expand visibility.
Tableau Pulse fits organizations already on Tableau that want metric monitoring rather than open-ended questioning, with the understanding that metric visibility is controlled by data source permissions rather than content permissions, and that data policies via virtual connections require the Data Management license.
ThoughtSpot suits teams that want table-level RLS applied consistently across search, Answers, Models, and Liveboards, and that will keep strict RLS enabled and audit their use of Bypass RLS on Models.
Acceptance Checklist
Use this checklist as a sign-off artifact. Each item should have a named owner and an evidence reference, not just a checkmark.
Enforcement layer confirmed: the team can state whether authorization for natural language queries happens at the warehouse, the semantic layer, the application, or some combination, and can cite the vendor page that says so.
Identity propagation confirmed: the team can state whether generated queries evaluate data access as the end user or a service account, and has tested the behavior with a restricted user.
Row-level controls tested: a restricted test user received filtered rows for questions whose full-population answer is known.
Column-level controls tested: masked or hidden columns remained masked or hidden in natural language responses, not only in dashboards.
Service-account and indexing behavior documented: the scope of any author, compute, or indexing account is recorded, along with the second enforcement layer that applies at query time.
Audit attribution verified: query history or audit logs show the test user's identity against the generated query, and an export has been produced.
Documented caveats acknowledged in writing: role-based limits, owner's-rights behavior, Bypass RLS scope, and content-permission gaps are recorded with the compensating control for each.
Policy maintenance owner named: one person or team owns base-table policies, semantic model permissions, and the re-test schedule.
Re-test cadence agreed: the test suite is scheduled to re-run after configuration changes and at a defined interval.
FAQ
Does RBAC alone secure natural language analytics?
No. RBAC controls which objects a principal can reach, but natural language adds generation, agent composition, and sometimes service accounts. Snowflake's RBAC does govern generated and executed SQL for Cortex Analyst, which is a strong guarantee, but it only holds if the underlying tables carry the row and column policies you intend. RBAC without row-level policy is object-level access, not row-level security.
Can a user prompt their way past row-level security?
Where the tool enforces at the data layer, documented behavior says no. Qlik states that users cannot expand their visibility through natural language questions in Qlik Answers. Snowflake states that row access policies on underlying tables propagate to semantic views and are enforced. Databricks states that Unity Catalog evaluates data access as the end user's identity. Where enforcement is only at the application layer, the answer depends on that layer's implementation, which is why the test procedure above includes direct elicitation attempts.
Is a row limit the same as authorization?
No. A row limit bounds how much data is returned; it does not determine which rows. A user who should see only their region's rows and receives the first 100 rows of the full table has received unauthorized data, just less of it.
What is the difference between owner's rights and user's rights in a semantic layer?
With owner's rights, a user with access to the semantic object does not need separate access to the underlying tables; Snowflake semantic views work this way. With user's rights, the query runs with the asking user's privileges and requires those privileges on the underlying objects. Owner's rights simplifies grants and lets policies on base tables do the enforcement work, but it also means a missing base-table policy is not compensated for by a table grant.
How often should permission tests be re-run?
After any change to workspace roles, semantic model permissions, base-table policies, agent sharing, or indexing configuration, and at a regular interval you define. Because permission models interact across layers, a change in one layer can alter effective access in another without any change to the natural language feature itself.
Verdict
No single tool wins on every criterion, and any comparison that declares one does so by choosing criteria after the fact. The decisive factors are narrower: whether authorization is enforced at the layer the generated query actually reaches, and whether the asking user's identity propagates to that layer.
On those factors, the warehouse-native options present the most durable story for organizations already standardized on them. Snowflake Cortex Analyst generates SQL that adheres to Snowflake RBAC, with row access and masking policies propagating from base tables to semantic views, subject to the owner's-rights obligation to define those policies on the tables. Databricks Genie separates compute credentials from data access, evaluates data access as the end user through Unity Catalog, and attributes each query to that user in query history. Both inherit a policy store you already operate.
Semantic-layer-native options are the right answer for organizations whose policy lives in the model. Looker composes queries through LookML so access filters, access grants, and user attributes apply, with the documented caveat that shared data agents still require underlying model permissions. Power BI Copilot uses the signed-in user's permissions and continues to apply RLS and OLS, bounded by the documented limitation that RLS only restricts Viewer-role users.
Qlik Answers, Tableau Pulse, ThoughtSpot, and Amazon Quick each document a specific, testable behavior: Section Access enforced independently of indexing scope, data source permissions controlling metric visibility with RLS respected, table-level RLS under strict application by default, and Enterprise-edition dataset RLS with a clear distinction between owners and readers.
The one test that most reliably exposes a weak implementation is the missing-grant scenario. Create a user who can reach the semantic view, agent, or dataset but not the underlying table, ask a question that should return filtered rows, and inspect both the answer and the query log. A tool that enforces at the data layer returns the filtered answer and attributes the query to that user. A tool that does not will show you exactly where its authorization actually lives.