
Which Platforms Combine Keyword and Vector Search Well — and How Costs and Latency Hold Up at Scale
How to compare hybrid search platforms on fusion model, cost structure, latency at scale, and usage metering — with an acceptance checklist and test harness for validating vendor claims.
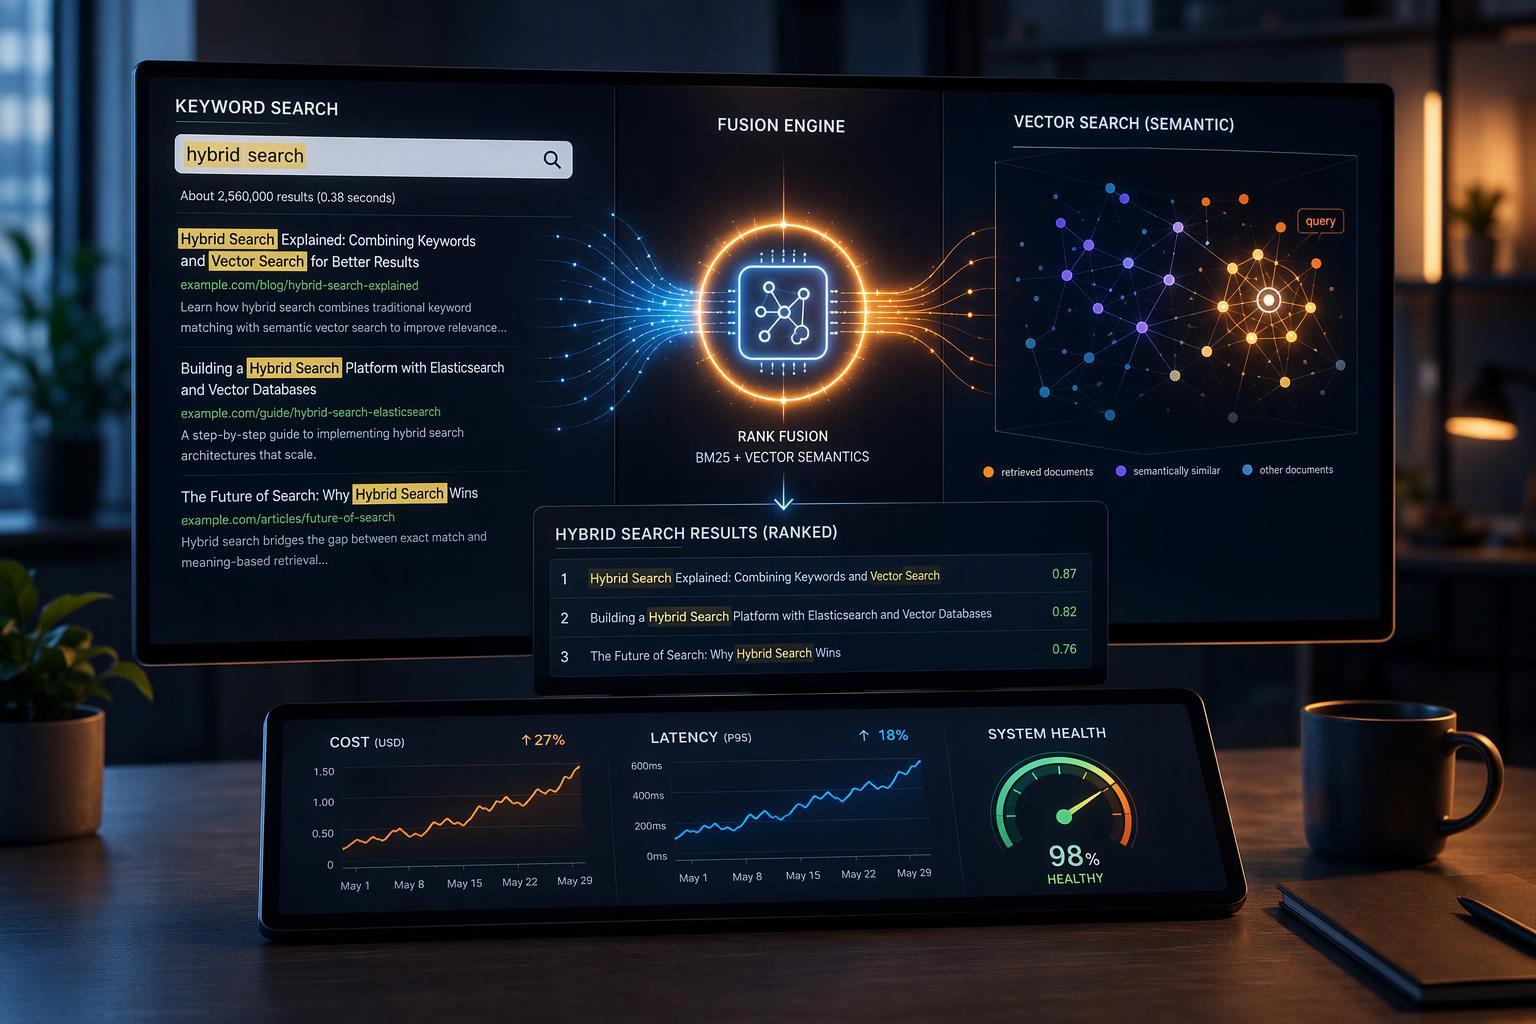
Hybrid retrieval demos well. A query that misses on exact terms gets rescued by the dense leg; a query that drifts semantically gets anchored by BM25. The demo takes an afternoon. The budget conversation takes a quarter, and it usually arrives with two questions that look unrelated but are not: which platform fuses keyword and vector results well, and what happens to cost and latency when the corpus and query volume grow.
Treat them as one question. Fusion quality decides how many candidates you must retrieve to hit your relevance bar, and candidate depth is a direct cost and latency input. A platform whose fusion is weak forces you to widen the candidate pool, pay for deeper scans, and wait longer — or accept worse results. Conversely, a platform with excellent fusion and opaque metering leaves you unable to explain the bill to the teams generating it.
This guide evaluates hybrid platforms on five criteria: the fusion model and where fusion executes, the cost structure and which billing dimensions scale with corpus versus query volume, latency shape at concurrency, attribution and metering granularity, and operational fit. Vendor-published performance figures appear here as claims to validate in your own environment, not as facts to adopt. The closing sections give you a test harness and an acceptance checklist to do exactly that.
Evaluation Criteria: How We Compare Hybrid Platforms
Define the criteria before naming a platform. Otherwise the comparison collapses into feature lists, and feature lists do not tell a budget owner where the money goes.
Fusion model. Two families matter. Rank-based fusion, principally reciprocal rank fusion (RRF), combines result lists by position and discards score magnitude. Score-based fusion normalizes each retriever's scores and combines them with weights. The distinction is not academic: rank fusion is robust when scores are incomparable, while score fusion can preserve information that ranks throw away — but only if you have tuning data and a normalization scheme. Equally important is where fusion executes. Engine-side fusion runs inside one request; client-side fusion requires two searches and a merge in your application. That architectural choice determines whether hybrid bills as one operation or two, and whether you can attribute the spend to a single request.
Cost structure. Enumerate the billing dimensions before comparing prices. Typical dimensions include serving compute, storage, embedding tokens at ingest and at query time, rerank searches or tokens, egress, and downstream LLM tokens. The question for a budget owner is which of these scale with corpus size and refresh cadence, and which scale with query volume and candidate depth. A platform that charges mostly for storage behaves very differently from one that charges per read unit when your traffic doubles.
Latency shape. Separate index build and refresh latency from query-time latency. Build latency is driven by corpus size, embedding throughput, segment merges, and refresh interval. Query latency is driven by candidate count, cache hit ratio, concurrency, shard fan-out, and whether embedding or reranking happens inline. A single-query benchmark number tells you almost nothing about p99 under load, and cold-cache behavior can dominate the first query after an idle period.
Attribution and metering. Ask whether the platform exposes usage data at a granularity you can tag — per query, per workload, per endpoint — and whether that data lands somewhere you can join it to tenant and application identifiers. Without this, cost allocation becomes an estimation exercise.
Operational fit. Self-managed engines give you control over tuning and placement but put capacity planning on your team. Managed services absorb operations but constrain the levers you can pull. For FinOps purposes, the question is who owns the cost when utilization is low.
Summary Comparison Matrix
The table below summarizes platform archetypes against the criteria above. Cells are structural descriptions drawn from vendor documentation, not benchmark results or price quotes. Validate latency and cost in your own environment before committing.
Archetype | Fusion model | Where fusion runs | Primary cost drivers | Latency behavior at scale | Attribution granularity | Best fit |
|---|---|---|---|---|---|---|
Elasticsearch / OpenSearch | RRF (rank-based) and, in OpenSearch, score-based normalization and combination | Engine-side, in one request | Ingest and search compute units, storage | Search capacity has a billed baseline even when idle; query load scales consumption | Billing dimensions by ingest, search, storage | Teams already operating these engines |
Vespa | Rank and linear-normalization fusion in ranking phases | Engine-side | Serving compute, storage | Tuned per rank profile; global-phase reranking adds cost | Self-managed telemetry | Teams needing fine ranking control |
Weaviate | relativeScoreFusion (normalized weighted sum) or rankedFusion, with an alpha parameter | Engine-side | Compute, storage | Depends on deployment model | Depends on deployment | Teams wanting tunable score fusion |
Qdrant | RRF and distribution-based score fusion (DBSF); multi-stage prefetch | Engine-side, with per-shard caveats | Compute, storage | Prefetch depth drives work per query | Depends on deployment | Multi-stage retrieval pipelines |
Pinecone | RRF documented as a client-side pattern; single-request hybrid via text-match filter plus dense rank | Client-side or single request | Read units, write units, storage, egress, embedding, reranking | Serverless; scales with namespace size | Usage-based metrics per index | Managed simplicity with usage metering |
Azure AI Search | RRF across hybrid queries | Engine-side | Dedicated: Search Units per hour (R×P). Serverless: Compute Units per hour | QPS tapers as index exceeds a vector search unit; 429s at capacity | Cost Management exports and request charge headers | Teams on the Azure stack |
Databricks AI Search | Vector and hybrid retrieval | Engine-side | Indexes (storage) and endpoints (serving) | Vendor-published ranges by SKU, vector count, dimension | Queryable billing usage with workload breakdowns | Teams consolidating on a lakehouse |
MongoDB Atlas | $rankFusion and $scoreFusion, plus $rerank | Engine-side in an aggregation pipeline | Cluster compute, storage | Follows cluster sizing | Cluster-level | Teams with data already in MongoDB |
Postgres / Lakebase | Rank fusion across BM25 and vector candidates in one SQL statement | Engine-side | Compute units, storage | Cache ratio and candidate limit dominate | Database-level telemetry | Apps keeping search next to transactional data |
Caption: Entries summarize vendor documentation as of this writing. Latency and cost cells describe structure, not measured performance. Vendor-published figures are claims to validate.
Fusion Model: RRF, Weighted Scores, and Where Fusion Actually Runs
A hybrid query runs two retrievers. The lexical leg scores documents with BM25, which rewards term overlap and exact matches — product codes, names, dates, specialized jargon. The dense leg embeds the query and finds semantically similar passages, which catches paraphrases and synonyms the inverted index misses. Fusion turns two ranked lists into one.
Rank-based fusion. RRF scores each document by summing 1/(k + rank) across every list it appears in. Elasticsearch exposes this through an rrf retriever with rank_constant (default 60) and rank_window_size parameters, and the documentation notes that each child retriever carries equal weight. OpenSearch implements RRF through a score ranker processor with the same rank constant. Azure AI Search merges hybrid results with RRF. Because only position matters, RRF needs no normalization and no per-signal weights, which is why Pinecone's documentation calls it a strong default for combining full-text and dense results.
The cost of that convenience is information loss. OpenSearch's own comparison table puts it plainly: the rank-based processor discards score magnitudes, so a document that outscores the next by a small margin is treated the same as one that outscores it by a large margin. The score-based normalization processor preserves those margins and exposes normalization techniques (min-max, L2, z-score) and combination techniques (arithmetic, geometric, harmonic mean) plus weights.
Score-based fusion. Weaviate's default relativeScoreFusion normalizes each retriever's output so the highest value becomes 1 and the lowest becomes 0, then takes a scaled sum, with an alpha parameter to shift weight between the legs. Vespa's hybrid tutorial uses linear normalization and reciprocal rank functions in a global ranking phase. MongoDB exposes both $rankFusion and $scoreFusion as aggregation stages, with per-query weights and an optional $rerank stage. Qdrant warns that a fixed alpha over raw scores is unreliable because dense and BM25 scores live on different scales that shift per query, and offers RRF and distribution-based score fusion as alternatives.
The research picture is workload-dependent. Bruch et al. found that a convex combination of normalized scores outperformed RRF on both in-domain and out-of-domain datasets, and that RRF is sensitive to its parameters. They also showed that the choice of normalization scheme matters less than the fact of normalizing at all, since linear transformations can be mapped onto one another. The practical reading: RRF is a defensible default when you have no tuning data, and score fusion is worth the tuning effort when you do.
Where fusion runs. Engine-side fusion executes both retrievers and the merge inside one request. Pinecone documents the alternative: RRF applied in your client after separate full-text and dense searches run. That pattern is portable across any two search APIs, but it doubles round trips and, as the cost section explains, can double billed reads. Client-side fusion also complicates attribution, because one logical user query becomes two billable operations that must be correlated in your own telemetry.
Filtering. Pre-filtering restricts candidates before ranking; post-filtering removes results after. Azure AI Search exposes vectorFilterMode and notes that with the semantic ranker you probably want post-filtering, but you should test which behavior suits your queries. The choice affects both quality and cost, because a pre-filter that shrinks the candidate set reduces the work the vector leg performs.
Cost Structure: What Scales With Corpus Size vs. Query Volume
Retrieval cost is not one number. It is a stack of layers with different scaling behavior, and modeling it means separating them.
Storage and index build scale with corpus size and refresh cadence. Every re-embedding pass, every index rebuild, and every segment merge consumes resources proportional to the data, not to traffic. Serving compute, query-time embedding, and reranking scale with query volume and candidate depth. A corpus that doubles overnight does not change your per-query serving cost; a traffic spike does. Egress scales with response size and cross-region traffic. Downstream LLM tokens scale with how many retrieved passages you feed the model, which is a function of your top-k and chunk size.
Vendor billing structures illustrate the shapes. Databricks AI Search bills two resources: indexes that store vectors, and endpoints that serve queries. One standard endpoint's vector search unit covers up to 2 million vectors at dimension 768, or the equivalent — 1 million vectors at dimension 1536 also counts as one unit. Multiple indices can share one endpoint, which the documentation notes can lower total cost for smaller workloads. Pinecone meters read units, write units, storage, and egress, with imports, backups, embedding, and reranking billed separately. Its documentation makes a billing-relevant distinction: a hybrid search that narrows candidates with a text-match filter and then ranks with a dense vector search is billed as one read request, while running separate keyword and dense searches and merging client-side is billed as two. Azure AI Search offers Dedicated capacity billed per hour in Search Units (replicas × partitions) and Serverless capacity billed in Compute Units per hour driven by query complexity, index size, data volume, and operation type, with vectorizers, semantic ranker, and agentic retrieval billed on their own units. Elasticsearch Serverless bills ingest VCUs, search VCUs, and storage; ingest VCU billing scales to zero during idle periods, but search VCU billing does not — a baseline of search capacity is always provisioned and billed at a reduced rate when idle, determined primarily by the Search Power setting and the search-ready dataset size.
These are billing mechanics, not cost predictions. The same workload can land very differently across them depending on whether it is storage-heavy or query-heavy.
Candidate depth is the lever you control. Databricks published a sizing study from Slide Hub, an internal app searching roughly 700 presentations, that illustrates the tradeoff. The app shipped with 1,000 candidates per method. Reducing the candidate limit to 200 preserved 90.5% of the top-10 results while cutting pages touched to one-third. A cold search at 200 candidates took 2.9 seconds end to end; a repeat search took 40 milliseconds. That is one team's reported result on one workload, not a general rule — but it is exactly the experiment a buyer should run, because the knee of the curve is where cost and quality stop trading against each other.
Latency at Scale: Separating Build Time From Query-Time p95/p99
Latency is a distribution, and the two distributions that matter are build time and query time. Conflating them produces procurement decisions that look sound and fail in production.
Build and refresh latency is a function of corpus size, embedding throughput, segment merges, and refresh interval. The Databricks study gives a concrete ingest figure: embedding 32.9 million MIRACL passages with a 1024-dimension model on one self-hosted A10G GPU ran at 379 passages per second, taking 2.95 GPU-hours, against $48.87 for the same work on a model-serving endpoint. Those numbers describe one model on one GPU; they illustrate the shape of ingest cost, not a benchmark for your corpus. Refresh cadence multiplies that cost: near-real-time indexing keeps results fresh but adds segment churn and merge load, while batch reindexing is cheaper and staler.
Query-time latency depends on candidate count, cache hit ratio, concurrency, shard fan-out, and whether embedding or reranking happens inline. Databricks' AI Search performance guide presents expected ranges across SKU, vector count, and dimension — for example, 20 ms at 10K vectors and 768 dimensions on the standard SKU, rising to 40 ms at 10M vectors and 50 ms at 100M, with QPS plateauing around 30 as the index exceeds a single vector search unit. The guide is explicit that performance is a range depending on workload characteristics, configuration, and client implementation, and that its numbers assume self-managed embeddings; managed embeddings add a model-serving call at query time. Treat the table as vendor-published guidance to reproduce, not as a specification.
The guide also documents two behaviors worth designing around. When the system reaches 100% QPS capacity it returns 429 errors, and without proper backoff the application can become unresponsive. And increasing num_results by 10x can double query latency and cut QPS capacity by roughly 3x depending on index size and configuration — a direct link between the top-k you request and the throughput you can sustain.
Cold cache and scale-to-zero change the p95 story. In the Slide Hub measurements, a cold search at 200 candidates took 2.9 seconds against 40 milliseconds for a repeat, with about 1 second spent waiting for the endpoint to wake and roughly 0.3 ms per page read from storage. The Databricks performance guide advises avoiding scale-to-zero for production for this reason. If your design scales to zero, your p95 includes wake-ups.
Client-side factors can dominate before the engine does. Slide Hub reached 45 requests per second at 2.4 seconds p95 without a connection pool, and 85 requests per second at 0.7 seconds p95 with one. The engine did not change; the client did. The same study found that from 8 compute units upward the application was the limit, and a larger app with four workers reached at least 662 requests per second where the load generator became the bottleneck. Sizing the query first, then the database, then the app, is the order that avoids paying for capacity you cannot use.
The number to contract against is p99 under your target concurrency with your candidate depth and cache behavior — not a single-query latency figure from a datasheet.
Cost Attribution and Usage Metering: From Tags to Chargeback
Attribution is a design choice, and it is easier to design before traffic arrives than after the first invoice dispute.
Tag at the request level. Every retrieval call should carry tenant_id, app_id, feature, and query_class. These identifiers are what let you slice a shared bill by consumer. Without them, a pooled endpoint produces one number and no explanation.
Emit a metering event per query. A workable schema: timestamp, tenant, application, index or collection, candidate counts per retrieval method, embedding tokens in and out, documents reranked, returned k, latency, cache state, and billed units where the platform exposes them. This event is the join key between platform billing data and business context. Where a platform's native granularity is insufficient, meter at the gateway in front of it.
Split embedding spend by owner. Ingest embeddings are a content-engineering cost driven by corpus size and refresh cadence; query-time embeddings are a serving cost driven by traffic. Different teams control each, so they should appear on different lines.
Expect approximation. The FinOps Foundation's allocation capability defines strategies to assign and share cost using accounts, tags, labels, and other metadata, and its AI guidance is candid that tracing which application, feature, or agent consumed model output is hard, with no accepted method for multi-agent workloads. Design for approximation and document the allocation rule rather than pretending to precision you cannot achieve.
Sequence showback before chargeback. Start with visibility: publish per-tenant and per-application consumption so teams can see what they use. Agree on allocation rules for shared resources — Databricks notes multiple indices can share one endpoint to lower cost, and Azure notes that combining workloads on Dedicated capacity improves utilization, both of which create shared cost that must be split by rule. Move to chargeback once those rules survive a quarter without renegotiation.
Use native billing exports where they exist. Databricks exposes system.billing.usage with a workload_type breakdown separating ingest, serving, and storage, queryable with SQL. That is the kind of granularity that makes attribution tractable. Where a platform offers only aggregate billing, your gateway metering carries the load. The FinOps Foundation's Data Cloud Platforms guidance makes the same point at the category level: connect billing exports with unit consumption — credits, DBUs, slots — and apply tagging at the query, job, workspace, or project level to attribute cost in shared environments.
Why Seat-Based Budgeting Fails for Retrieval Workloads
A seat-based budget assumes cost scales with named users. Retrieval cost does not. It scales with query volume, candidate depth, embedding tokens, rerank volume, and index refresh cadence — and every one of those can grow without a new seat being provisioned.
Single source, single corpus: Databricks' throughput test sent hybrid queries directly to Lakebase Postgres over 4M passages at 64 concurrent connections, one query per connection at a time, with the load generator's CPU near zero. Median wait is the time a connection waited for its answer. These are database-only figures without the application layer, so they bound the engine, not the end-to-end user experience.
Consider what agents change. An MCP server or an automated caller issues queries on behalf of a workflow, not a person. The Slide Hub study is a small illustration: the same search backs both a human-facing search bar and an agent tool, and the agent's traffic consumes the same metered resources. A seat count would not have predicted the load. The FinOps Foundation's AI guidance reaches the same conclusion structurally: top-down budgets are less accurate for AI workloads, and unit economics need token-based units plus workload and value metrics such as cost per resolved case.
Budget on unit economics instead. Three measures cover most retrieval programs: cost per 1,000 queries, cost per resolved answer or successful task, and cost per tenant. Each requires a volume forecast — queries per month, average candidate depth, average returned k, rerank rate — and each can be validated against the metering events described above. Keep a seat-based view only for the human-facing layer, where it still describes something real.
The practical consequence for a budget owner is that the forecast conversation shifts from headcount planning to traffic planning. That is a harder conversation, but it is the one that matches how the bill actually moves.
Acceptance Checklist and Test Harness
The checklist below is designed to be run on a representative corpus sample before signing, not after. Each item produces a number you can put in a cost model.
Checklist
Reproduce a hybrid query in both fusion modes — rank-based and score-based where the platform offers both — on your own corpus sample with graded relevance judgments.
Measure top-k overlap between candidate depths (for example 1,000 versus 200) to find your cost/quality knee. Databricks' 90.5% top-10 overlap at one-third the page reads is the shape to look for.
Measure cold versus warm p95 and p99 at target concurrency, with and without connection pooling, and with scale-to-zero enabled or disabled according to your intended design.
Confirm whether a hybrid query bills as one request or two. Pinecone's documentation is explicit that the filter-plus-dense pattern bills as one read while client-side merging bills as two; verify the equivalent for your platform.
Confirm which usage dimensions the platform exports, at what granularity, and whether they can be joined to your tenant and application identifiers.
Test filter behavior — pre-filter versus post-filter — on a filtered query set, since the choice affects both quality and cost.
Verify 429 and backoff behavior at capacity, and confirm your client handles it without becoming unresponsive.
Verify that embedding and rerank charges appear where you expect them, at ingest and at query time.
Harness design. Four components make the checklist runnable: a fixed query set with graded relevance judgments so quality is measured rather than felt; a load generator running in the same region as the service so network latency does not contaminate the numbers; a metering sidecar that logs the event schema from the previous section on every request; and a cost model spreadsheet fed by the platform's billing export, so measured usage converts to forecast spend under your volume assumptions. Keep the harness vendor-neutral — the same query set and load profile should run against any candidate.
Who Should Choose Which
Self-selection should follow constraints, not brand preference. The mapping below starts from where you already are and what you can operate.
Already running Elasticsearch or OpenSearch. Engine-side RRF is available in one request, and OpenSearch adds score-based normalization and combination if you want to tune. You inherit existing operations and monitoring. The tradeoff is that search capacity carries a billed baseline even when idle, so low-traffic periods still cost something.
Need fine-grained ranking control. Vespa, Weaviate, and Qdrant expose score fusion with normalization and weighting, and Qdrant adds multi-stage prefetch with per-shard caveats for fusion placement. These reward teams with tuning data and penalize teams without it — score fusion without a validation set is guesswork.
Want managed simplicity on a cloud AI stack. Azure AI Search offers engine-side RRF, Dedicated or Serverless billing, and separate units for vectorizers and semantic ranker. Databricks AI Search offers index and endpoint billing with queryable usage data. Both publish latency ranges you should reproduce rather than adopt.
Data already in MongoDB. Atlas exposes $rankFusion and $scoreFusion as aggregation stages with per-query weights and an optional rerank stage, which keeps retrieval next to the data and avoids a second system to operate.
Optimizing for consolidation and attribution. If retrieval sits next to the data and the billing exports, attribution gets simpler because the same telemetry covers both. That is the criterion to evaluate — whether query-level usage data, workload telemetry, and billing exports live in one place you can query. Singdata's lakehouse positions unified storage, compute, and governance as a single architecture; whether that helps your attribution depends on the metering granularity you can actually export, which is a question for the acceptance checklist, not a headline claim.
Where each archetype loses. Client-side fusion is portable across any two search APIs but doubles billing events and complicates attribution. Self-managed engines give control but put capacity planning on your team. Managed services absorb operations but limit the levers you can pull when utilization is low. Pick the loss you can live with.
FAQ
Is RRF always the right default? No. It is a strong default when scores from different retrievers are incomparable, because it needs no normalization or tuning. Score fusion can outperform it when you have tuning data, and the research found RRF sensitive to its parameters.
Does hybrid always cost double? Only when implemented as two separately billed requests. Engine-side fusion runs both retrievers and the merge in one request; Pinecone documents that a filter-plus-dense hybrid bills as one read while client-side merging bills as two.
How do I compare vendor latency numbers? Don't compare them directly. Reproduce them at your concurrency, candidate depth, and cache behavior, and contract against p99 under load rather than a single-query figure.
What is the minimum viable metering schema? Tenant, application, query class, candidate counts per method, token counts, latency, and cache state — emitted per query and joinable to the platform's billing export.
Can I attribute shared endpoint costs? Yes, with a documented allocation rule. Start with showback so teams can see consumption, agree on how pooled resources are split, and move to chargeback once the rules hold.
Conclusion
The decision frame is four statements. Fusion quality is testable — run both modes on your corpus and measure. Cost is modelable by layer — separate what scales with corpus from what scales with queries. Latency is a distribution — measure p99 under concurrency, including cold starts and client-side effects. Attribution is a design choice — tag at the request level and meter before traffic arrives.
Pick the fusion model your workload validates rather than the one with the strongest documentation. Budget on unit economics — cost per 1,000 queries, cost per resolved answer, cost per tenant — with a volume forecast that accounts for agents and automated callers. Instrument metering before scaling query volume, because retrofitting attribution onto an unexplained bill is the expensive path.
The next action is one step: run the acceptance checklist on a representative corpus sample before you sign.
Previous posts
1. Medallion Architecture: What Changes Between Bronze, Silver, and Gold? — https://singdata.com/trending/medallion-bronze-silver-gold
2. How Much Data Preparation Is Hidden in Your BI Reports? — https://singdata.com/trending/hidden-data-prep-in-bi-reports
3. How to Migrate from ETL to ELT Without Breaking Reporting or Agentic AI Freshness — https://singdata.com/trending/2026-11-04-elt-file-first-ingestion