
How Much Data Preparation Is Hidden in Your BI Reports?
A practical way to count the repeated cleaning, joins and de-duplication hidden behind BI dashboards, and to decide which preparation belongs in a shared, reusable data foundation.
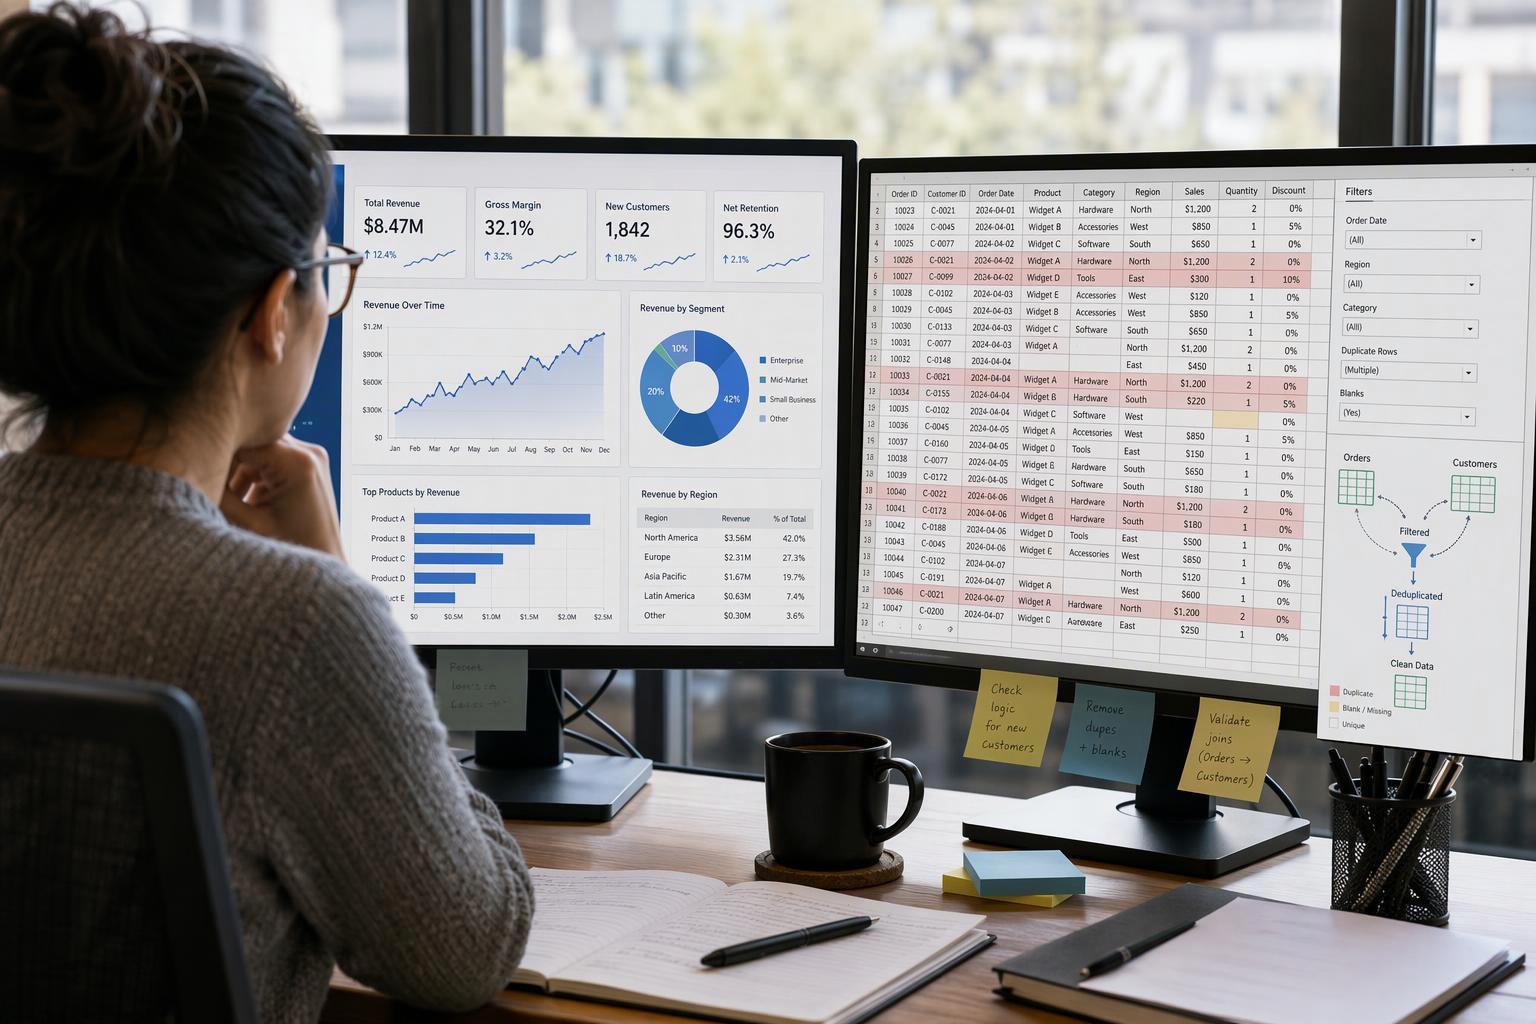
A finished dashboard shows one number per tile. Behind each tile sits a chain of work that the visual does not display: fields renamed and cast to the right type, timestamps moved into one timezone, customer records matched across two systems, duplicate orders collapsed to one row, scope filters applied so the chart means what its title says. The dashboard is the visible tip; the preparation is the mass beneath it.
That preparation is real work, and in most report portfolios it is repeated work. The "how much" has no universal answer — it depends on how many reports you run, how many sources feed them, and how independently each one was built. What this article offers instead of a benchmark is a way to count the hidden preparation in your own reports, a comparison of two ways to organize it, and a practical boundary for deciding which steps belong in a shared layer and which should stay local to a single report.
The preparation that never appears on the dashboard
Hidden preparation is easier to recognize than to define. In most BI estates it falls into a small number of recurring categories:
Field standardization. Renaming columns to agreed labels, casting types, aligning units, and reconciling timezones so that a date means the same thing in every report.
Joins across sources. Bringing orders, customers, products and reference tables together, and deciding which table governs the grain of the result.
De-duplication. Collapsing repeated customer records, double-posted transactions or multiple source rows into one entity per report line.
Filtering and scope rules. Excluding test accounts, restricting to a region or period, or applying an eligibility rule that the visual itself never states.
Derived business fields. Computing margin, tenure, cohort month or a status flag from raw columns.
Business rule application. Encoding the organization's agreed treatment of refunds, trials, intercompany transactions or currency conversion.
None of these steps is a mistake. A report that skipped them would be wrong. The problem is visibility: once the visual renders, the logic that produced it disappears from view, so an audit that looks only at dashboards will systematically undercount the effort involved.
Where the steps live makes the undercount worse. Some preparation sits in the query that feeds the report, some in a semantic model or data source layer, and some in calculated fields defined inside the report itself. Tableau's guidance, for example, notes that its desktop tool can create joins and do basic data shaping, but points to a dedicated preparation tool when the work involves multiple joins, field renaming, type changes or several pivots — a division of labor that spreads preparation across tools (Tableau Help). If you inspect only one of those places, you see only part of the work.
Why the same cleaning gets done more than once
Duplication arises from a structural cause rather than carelessness. When each report is built independently against raw sources, each author re-derives the same standardization, the same joins and the same de-duplication, because there is no prepared asset to start from. Two analysts building a sales report and a margin report will each decide how to handle a cancelled order, and their decisions may differ in small ways that are invisible until the numbers are compared.
Vendors describe the alternative as recommended practice rather than a measured finding. Microsoft's documentation on dataflows frames reusable transformation logic as a design goal: create logic that many semantic models and reports can share, and persist it so that report creators do not each open separate connections to the same sources (Microsoft Learn). The same documentation recommends separating staging or extraction from transformation so that each output stays reusable by other processes (Microsoft Learn).
The consequences of skipping this are the ones practitioners recognize first. Effort is duplicated, because the same cleaning is authored several times. Definitions drift, because each copy can diverge slightly. And maintenance multiplies: a change in a source system or a business rule must be traced through every report that re-implemented the logic, not applied once. dbt Labs makes the same point from the transformation side, noting that when datasets do not follow standardized conventions, analysts risk duplicating work as they recreate similar transformations across projects, and that inconsistent metric definitions can produce conflicting reports (dbt Labs).
Two ways to organize the same work
The comparison that matters is not between good and bad practice but between two ways of organizing the same necessary work.
Illustrative example only, not observed data. A hypothetical portfolio of 20 reports, each performing six preparation steps, of which four are identical across all 20. Both bars count the same unit — preparation-step implementations — for the same reports and the same steps; only the location of the logic differs. No time or cost saving is implied.
Each report processes its own data. Every report connects to sources, standardizes fields, joins tables and de-duplicates independently. Each report is self-contained, which makes it easy to change without coordinating with anyone. The cost appears at portfolio scale: preparation effort grows roughly with the number of reports, the same logic exists in several places, and consistency depends on every author making identical choices.
Many reports reuse already-prepared data. The shared standardization, joins, de-duplication and business rules are built once in a lower layer, and reports consume that prepared output. Preparation effort for the shared portion is paid once rather than per report, definitions can be identical by construction, and a rule change has one place to be applied. The cost moves to coordination: the shared layer needs an owner, changes to it affect every dependent report, and report authors give up some freedom to shape data their own way.
The refresh dimension deserves care because it cuts both ways. Centralizing preparation can consolidate refresh scheduling and reduce repeated loads on the same source systems — Microsoft's guidance, for instance, suggests splitting tables into separate dataflows when they need different refresh schedules, which is only possible once the tables are managed in a shared structure (Microsoft Learn). But the same centralization means a shared layer's refresh now gates every dependent report. A delay or failure in the shared layer propagates to all of them, where previously one report's refresh problem stayed local. Tableau's documentation makes the same dependency explicit for published data sources: updates to a published data source flow to all connected workbooks (Tableau Help).
A worked illustration, clearly hypothetical: suppose a portfolio of 20 reports each performs six preparation steps, and four of those steps are identical across all 20. Under per-report processing, that is 120 step-implementations. Under a shared layer, the four common steps are built once and the two report-specific steps remain per report, for 4 + 40 = 44. The arithmetic is illustrative only — it assumes the steps really are identical, which is the question the next two sections help you answer.
What a reusable data foundation actually means
A reusable data foundation is a set of prepared, shared data assets — standardized fields, resolved joins, de-duplicated entities and agreed business definitions — that multiple reports consume instead of rebuilding. It is a description of what the data looks like when it reaches report authors, not a prescription for a particular architecture.
What it does:
Reduces repeated preparation, because the shared steps are implemented once.
Supports consistent definitions, because reports draw on the same prepared fields rather than each author's interpretation.
Gives one place to maintain shared logic, so a rule change is applied at the source of the definition.
What it does not guarantee:
It does not fix bad source data. If the underlying records are wrong, a shared layer distributes the same wrongness more consistently.
It does not remove the need for report-level work. Presentation logic, report-specific filters and one-off analysis still belong with the report.
It does not automatically make every metric consistent. Consistency requires that definitions are genuinely shared and governed; a shared layer that nobody maintains will drift like any other.
The dimensional modeling literature makes the last point precisely. Kimball's techniques note that conformed dimensions — defined once in collaboration with the business's data governance representatives and reused across fact tables — deliver analytic consistency and reduced future development costs because the wheel is not repeatedly re-created (Kimball Group). The consistency comes from the shared definition and the governance around it, not from the storage location alone.
Counting the hidden preparation in your own reports
Since no external benchmark can tell you how much preparation is hidden in your reports, measure it yourself. The method is an inventory, and it takes a few days for a portfolio of moderate size.
What to count, per report:
Standardization steps: renames, casts, unit conversions, timezone handling.
Joins, and which tables they connect.
De-duplication logic and the key it uses.
Filters and scope rules that change what the report means.
Derived fields and the formulas behind them.
Business rules applied, such as refund treatment or currency conversion.
Where to look: the report's query or SQL, the transformation steps in whatever preparation tool feeds it, the model's relationships and calculated fields, and any logic defined inside the report itself. Check all four locations; preparation tends to accumulate in whichever one the original author found convenient.
How to present it: build a table with one row per distinct preparation step and columns for a short description, where it lives, and the number of reports that perform it. Sort by the report count. The top of that list is your candidate set for sharing.
Preparation step (illustrative) | Where it lives | Reports performing it |
|---|---|---|
Normalize order timestamps to UTC | Query layer | 14 |
De-duplicate customer records on tax ID | Preparation tool | 11 |
Exclude internal test accounts | Report filter | 9 |
Compute gross margin | Calculated field | 6 |
Region-specific product mapping | Report query | 1 |
The numbers above are illustrative, not observed. Your inventory is your own measurement, and it is the only figure that should drive your decisions. The value of the exercise is not the total count but the distribution: steps performed by many reports are the ones where sharing pays, and steps performed by one report are the ones where it does not.
Deciding what to share and what to keep local
Sharing is not automatically better. The decision is a trade between reuse and flexibility, and the criteria below are recommended practice rather than measured rules.
Signals for sharing:
The step is used by more than one report. This is the strongest signal, and the inventory above quantifies it.
The definition should be identical everywhere — currency conversion, fiscal calendar, customer identity, revenue recognition.
The logic changes rarely. Stable logic amortizes the coordination cost of a shared layer; volatile logic does not.
Signals for keeping local:
Report-specific filtering or scope that only that report needs.
One-off analysis or exploratory work where the logic is still being decided.
Logic in flux, where centralizing would force every dependent report to absorb each iteration.
The trade-offs to weigh honestly: a shared layer adds coordination and change-management overhead. Someone must own it, review changes and communicate them. A shared change reaches every dependent report, which is efficient when the change is correct and disruptive when it is not. Microsoft's guidance on managed self-service BI describes the goal as finding the right balance, leaning toward relatively few shared models and creating new ones when it makes sense — explicitly rejecting both extremes of one model for everything and one model per report (Microsoft Learn).
The practical test: if two reports would need to change together whenever the logic changes, the logic belongs in a shared layer. If a change to one report should never affect another, keep it local.
Where to start
Start with a bounded scope rather than a platform decision. Pick five to ten reports that matter to the business and that were built by different people. Run the inventory from the earlier section on each: list the preparation steps, note where each one lives, and count how many reports repeat it.
Then sort the list by report count and look at the top few entries. Those are your candidates for a shared layer — not because sharing is a principle, but because your own measurement shows the work is being repeated. Before committing, check two things for each candidate: whether the definition genuinely should be identical across the reports that use it, and whether the logic is stable enough that centralizing it will not create a coordination burden larger than the duplication it removes.
If the answer to both is yes, you have a concrete first scope: a small set of shared preparation steps, consumed by a known set of reports, with a measurable before-and-after in the inventory. That is a more defensible starting point than a platform migration, and it produces evidence you can use to decide what comes next.
FAQ
Is hidden preparation always waste? No. Some preparation is necessary and specific to a single report — a particular scope filter, a one-off cohort definition, a presentation-level calculation. The waste is not preparation itself but preparation repeated identically across reports without a shared definition.
Is the goal to share everything? No. The aim is the right balance. Shared layers add coordination and change-management overhead, and a shared change reaches every dependent report. Logic that is volatile, report-specific or still being decided is usually better kept local.
Does a shared foundation guarantee consistent numbers? Only when definitions are genuinely shared and governed. A shared layer that nobody owns or maintains will drift like any other. Consistency comes from the shared definition and the governance around it, not from the storage location alone.
Can I estimate the hidden preparation without a full audit? Yes, approximately. Inventory a representative sample of reports, count the preparation steps and how often each repeats, and extrapolate cautiously. Treat the result as your own measurement with a stated sample, not as a benchmark.
Does centralizing preparation make refresh simpler? It can consolidate refresh scheduling and reduce repeated loads on source systems, but it also means a shared layer's refresh gates every dependent report. Both effects are real, and the right choice depends on how much downtime your consumers can tolerate.