
Most of an Agent's Bill Is Paid Before It Reasons
A single team's rebuild cut tokens per LLM call from 14,200 to 1,650 on the same pages. Why ingestion cost, not model price, drives agent bills.
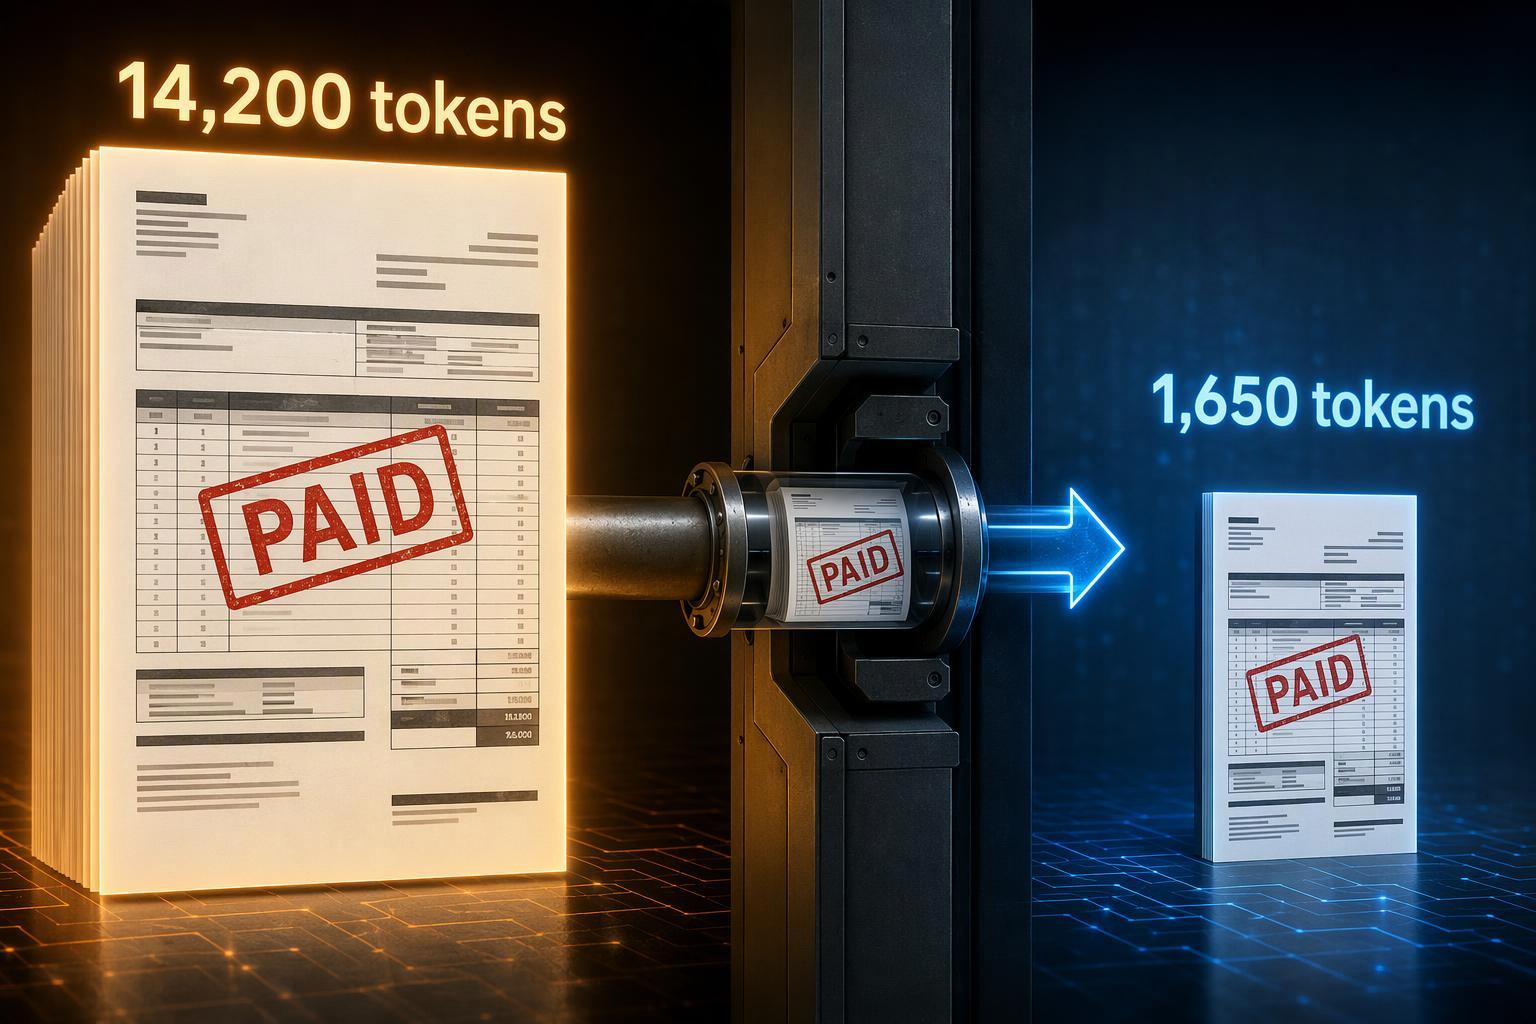
A team rebuilt its scraping pipeline and pointed it at the same pages it had always scraped. The page did not change. The question did not change. What changed was how much of the page reached the model: tokens per LLM call fell from 14,200 to 1,650. That is not a prompt-tuning result. It is the difference between handing a model a page and handing it the part of the page that answers the question.
The numbers come from a single team's self-reported before/after comparison, published on HackerNoon on November 4, 2026, by Hamed Hosseini. The write-up is self-labeled as AI-assisted writing and has no third-party replication. Treat it as one team's account of its own rebuild, not as an industry benchmark. Within that boundary, the account is unusually specific, and it points at something most cost conversations miss.
The claim of this article is that a large share of what teams call "the model is too expensive" is actually unstructured payload bought into the context window at token prices. The three costs at the ingestion layer — getting blocked, context bloat, and proxy bandwidth — do not fall when model prices fall. They scale with the number of targets. Price cuts touch only the last stage of the funnel. The leverage is deterministic pruning before the model is called, not a cheaper model after it.
The cost is incurred at a stage that has no line item
Most teams budget for the model. They watch tokens, they negotiate rates, they compare providers. The ingestion layer rarely appears as a line item, because it is spread across proxy invoices, compute for headless browsers, retries, and the token bill itself.
The source's failure structure makes the scale concrete. Roughly 78% of the target sites sat behind Cloudflare Turnstile, DataDome, or Akamai. Raw HTML ran 12,000 to 18,000 tokens per page. Residential bandwidth cost $8 to $15 per gigabyte. None of those three numbers is a model price. All three are paid before the model is called.
The methodological line that carries the argument is this: "A 2.4 MB e-commerce page usually contains under 4 KB of useful data." The ratio is the point. The pipeline was paying to move, render, and tokenize megabytes to recover kilobytes. The model was never the expensive part of that transaction; it was the last and smallest stage of it.
Three costs that move with target count, not model price
Take the three costs one at a time, because each has a different scaling behavior and none of them responds to a cheaper model.
Before/after figures from one team's self-reported rebuild, measured on 10,000 anti-bot-protected URLs over 7 days against a control arm of local Playwright plus generic residential proxies. Source: Hamed Hosseini, HackerNoon, November 4, 2026; self-labeled AI-assisted writing, no third-party replication. Not an industry average. The 74% cost reduction is derived from the $184.20/$47.50 pair.
Getting blocked. When 78% of targets sit behind an anti-bot perimeter, a naive pipeline spends requests on challenges it will not pass. The source's control arm — local Playwright plus generic residential proxies — achieved a 36.4% success rate. That means roughly two of every three requests were paid for and produced nothing usable. The cost per successful extraction was therefore far higher than the cost per request, and it rose with every target added.
Context bloat. Raw HTML at 12,000 to 18,000 tokens per page is bought at token prices. If the model is cheaper per token, the bill falls proportionally — but the payload is still 12,000 to 18,000 tokens. A price cut multiplies a large number by a smaller rate. It does not shrink the number. The source's rebuild cut tokens per call to 1,650 by pruning before the call, which is a different operation entirely.
Proxy bandwidth. Residential bandwidth at $8 to $15 per gigabyte is billed by volume, not by model. Downloading hero images, fonts, and analytics beacons across thousands of targets is a cost that a cheaper model does not touch at all.
The common structure: each cost is a function of how many targets you watch and how much of each target you pull. Neither variable appears in a model price sheet. When a provider announces a price cut, it changes the rate on the last stage of a funnel whose earlier stages are priced by volume and by target count.
Tokens per successful extraction is the missing unit
Cost per run hides the failure rate. Tokens per call hides the payload size. Neither captures what a team actually pays to get one usable record.
Consider the control arm. At a 36.4% success rate, the effective cost per successful extraction is roughly the cost per attempt divided by 0.364. The source reports cost for 10,000 operations falling from $184.20 to $47.50 after the rebuild — a 74% reduction. But the same rebuild also moved success from 36.4% to 99.4%. The cost per successful extraction fell by more than the headline cost figure, because the denominator changed too.
That is why tokens per successful extraction belongs next to success rate and cost per run. It is the unit that ties payload size to outcome. A pipeline that halves its tokens but fails half its requests has not improved. A pipeline that keeps its tokens and doubles its success rate has.
The source's method shows how the numerator moves. Stage one reads JSON-LD first — about 320 tokens, zero model calls. If a valid schema exists, the model never runs. Stage two applies density-based pruning to the remaining markup: strip script, style, svg, iframe, nav, and footer, score nodes by text-to-tag ratio, drop low-density containers, and emit the remainder as structured tables. The model receives structure, not noise.
The optimization order is inverted
The default sequence in most teams runs like this: build the pipeline, watch the bill, switch to a cheaper model, add caching, compress the prompt. Each step is reasonable. Each step also operates downstream of the stage where the payload was bought.
The source's own framing supports the inversion. Its conclusion is that "the hard part of autonomous agents is not the prompt. It is the ingestion layer: reaching the data, paying the minimum for it, and delivering it clean enough that a model can reason about it without inventing things." The rebuild did not start with the model. It started with routing — direct HTTP first, escalation only on failure — and with pruning before the call.
The order matters because the stages are not independent. A cheaper model applied to a 14,200-token payload still pays for 14,200 tokens. A pruned payload of 1,650 tokens makes every downstream model cheaper in absolute terms, whatever its rate. Optimizing the model first caps the savings at the model's share of the bill. Optimizing ingestion first changes the bill itself.
The honest case for the other side
The case for "just switch to a cheaper model, add caching, compress the prompt" is not stupid. Those moves are cheap, fast, and do not require touching a pipeline that already works. A model swap is a configuration change. Caching is a wrapper. Prompt compression is a library call. None of them requires an engineer to learn a target site's markup or maintain a pruning rule set. For a team with a working pipeline and a bill it dislikes, those are the rational first moves.
The recommendation in this article carries real costs, and they should be named.
Engineering time. Building structured-first extraction and density-based pruning is pipeline work. It has to be written, tested, and maintained. The source's rebuild involved tiered routing, a JSON-LD harvester, and a pruning stage — not an afternoon's work.
Per-site fragility. Pruning rules depend on markup. When a target site changes its structure, the rules can silently degrade. The source itself reports post-launch fixes for sticky session lockouts, canvas fingerprinting, and compounding retries — production exposes what benchmarks hide.
Discarded fields. Pruning removes content by a density heuristic. A field that looks like noise today may be the field someone needs next quarter. The source's own limitation is instructive: it notes that its structured-first approach works because retailers expose schema.org data for Google, and that the model never runs when a valid schema exists. That is a real dependency, not a universal guarantee.
The 74% cost reduction is a measured result on one specific target set and cannot be extrapolated as an industry average. The argument here is about the order of optimization, not about a number every team should expect.
What to do in the next two weeks
For data engineering and analytics leads, the actionable change is a metric and an order.
Promote tokens per successful extraction to a first-class metric alongside success rate and cost per run. It is the unit that makes the ingestion layer visible, and it is the one that a model price cut does not move.
Then fix the optimization order: ingestion layer first, model layer second.
A two-week action that fits inside a normal sprint:
Pick one daily-refreshed external source.
Record current tokens per page and success rate as a baseline.
Add structured-first extraction — JSON-LD or schema.org — plus tag pruning.
Run for one week.
Compare tokens per successful page and failure rate against the baseline.
The comparison is the deliverable. If tokens per successful extraction falls and the failure rate holds or improves, the ingestion layer was carrying cost that the model layer could not have removed.
Where the pruned output and the extraction results land matters for whether the improvement is measurable over time. In a lakehouse that holds both structured output and extraction results, incremental processing that touches only changed partitions makes unit cost recomputable and attributable per source. Singdata positions its lakehouse this way; any vendor performance or cost-reduction figure should be treated as vendor-stated, not independently verified, and validated in your own environment.
The landing is the same as the opening. Because the dominant cost occurs before the model reasons, optimization has to start at ingestion. Without it, every cheaper model cuts only a fraction of the bill while the failure rate stays near one third — and the resulting gaps get blamed on the source site.
FAQ
Why doesn't a cheaper model fix this?
A cheaper model lowers the rate per token. It does not change how many tokens you send, how many requests get blocked, or how much bandwidth you pay for. Those three costs scale with the number of targets and the size of the payload, not with the model's price. A price cut touches the last stage of the funnel; the ingestion layer sits before it.
How do you measure tokens per successful extraction?
Divide the tokens consumed over a period by the number of successful extractions in that period. Track it alongside success rate and cost per run, because the three move independently: a pipeline can cut tokens per call while its failure rate rises, and the ratio is what exposes that. The two-week procedure above gives you a baseline and a comparison point.
Is pruning rules-based or model-based?
In the source's method, it is rules-based and deterministic. Stage one reads JSON-LD with zero model calls. Stage two scores nodes by text-to-tag ratio and drops low-density containers by rule. The model receives the pruned structure rather than performing the pruning. That is what makes the cost predictable — and what makes the rules fragile when a target site changes its markup.
Previous posts
1. Medallion Architecture: What Changes Between Bronze, Silver, and Gold? — https://singdata.com/trending/medallion-bronze-silver-gold
2. How Much Data Preparation Is Hidden in Your BI Reports? — https://singdata.com/trending/hidden-data-prep-in-bi-reports
3. How to Migrate from ETL to ELT Without Breaking Reporting or Agentic AI Freshness — https://singdata.com/trending/2026-11-04-elt-file-first-ingestion