
How to Verify AI-Generated Numbers in BI Tools: A Buyer's Guide
A buyer's guide to BI tools with verifiable AI answers: six criteria for traceable, reproducible numbers, red flags and deal-breakers, and a golden-set trial acceptance test.
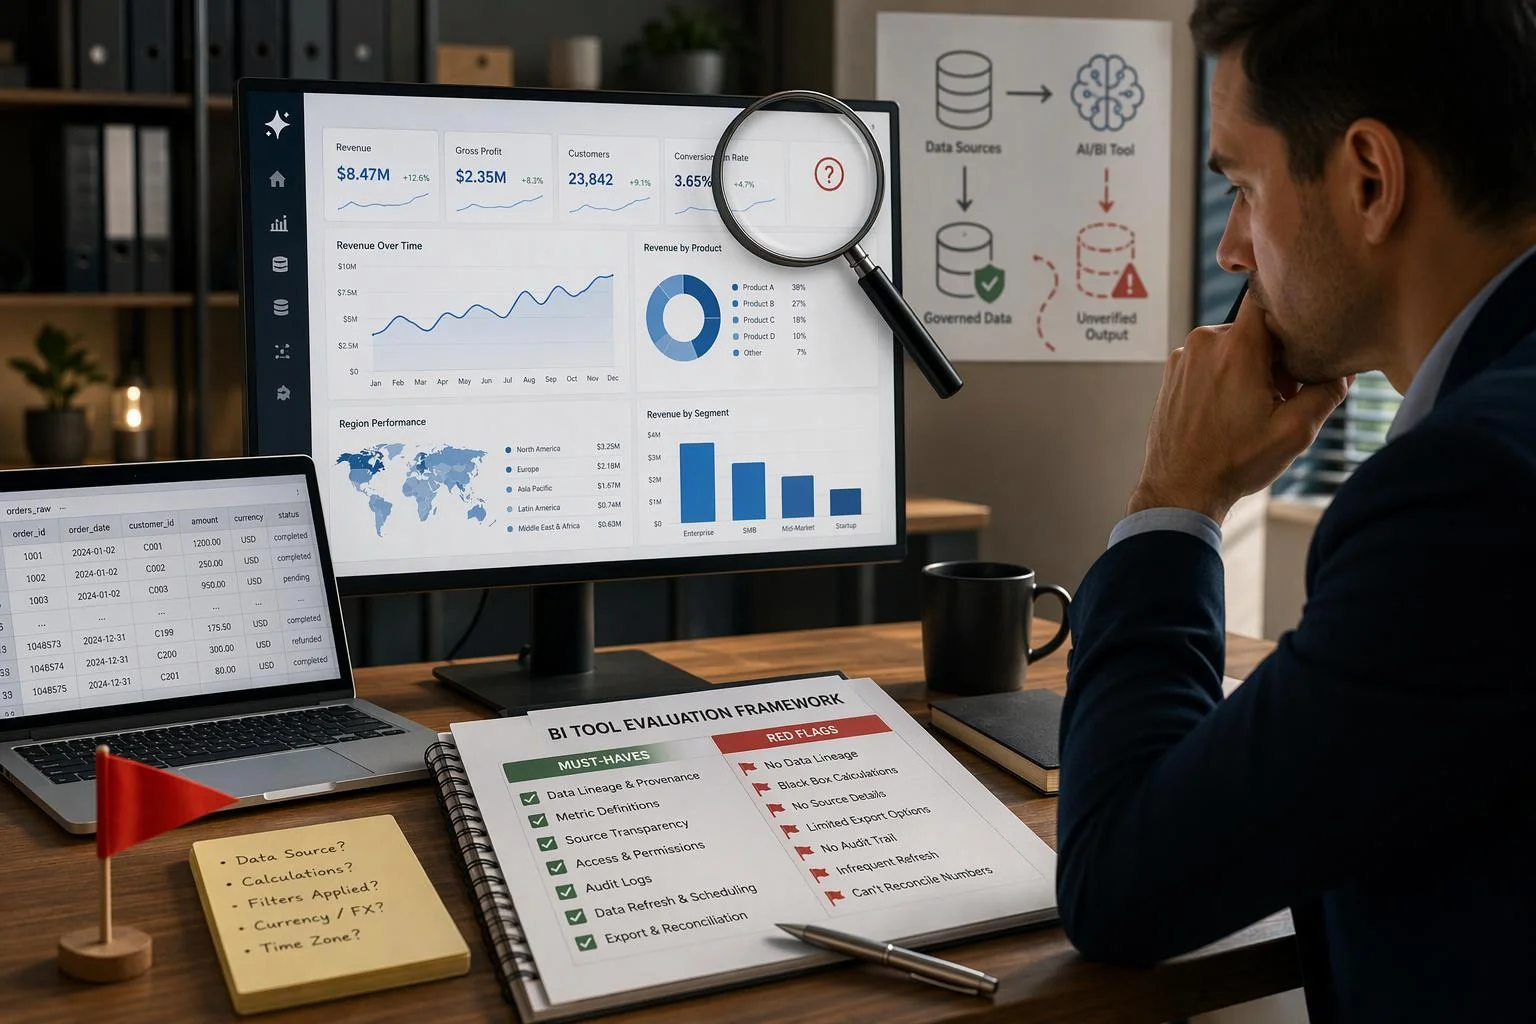
An AI BI answer can look completely authoritative and still never have been computed from your governed data. That is the specific fear worth designing around: not that the assistant is obviously wrong, but that a plausible number arrives with no query, no definition, and no way for anyone to check it.
The distinction that resolves most of this is simple. A number can be retrieved and computed — a query ran against your warehouse or semantic layer and returned a result — or it can be generated as text, where a language model produced digits that approximate what such an answer usually looks like. NIST's Generative AI Profile calls the second pattern confabulation and describes it as a natural result of how generative models work: they predict likely output rather than look anything up. The same document warns that models can also produce confabulated logic or citations that appear to justify an incorrect answer, which is precisely what makes an unverified figure feel trustworthy.
This guide gives you a buyer's sequence: assess what your team actually needs to verify, define six criteria a verifiable answer must meet, separate red flags from genuine deal-breakers, run a trial acceptance test, and then decide.
Start With Your Own Verification Needs
Before you compare tools, write down what verification has to mean in your organization. The useful prompts are about decisions, people, and obligations rather than features: which decisions will consume AI answers, who is accountable for checking them, what evidence those checkers need, and which regulatory or audit requirements apply to the records you keep.
Map the consequence level of each answer
Verification rigor should scale with what the number feeds. A dashboard exploration tolerates a lighter check than a figure that goes into a board deck, a regulatory filing, or a loan decision.
NIST notes that risks of confabulated content may be especially important to monitor when GAI is integrated into applications involving consequential decision making. That is the justification for tiering rather than applying one standard everywhere: sort your intended use cases into low, medium, and high consequence, and let the high tier drive your requirements. If a tool cannot meet the high tier, it may still be fine for the low one.
Define what "verifiable" means for your team
A workable definition to carry into every demo: a verifiable answer is one where an independent person can reproduce the number from the same governed data and see the logic that produced it.
Keep two properties separate. Reproducibility means the same question against the same source returns the same number, and someone else can re-run the logic to confirm it. Explainability means the tool shows how it interpreted the question and which fields and filters it used. Both matter, and they are not the same thing: a tool can explain its reasoning fluently while returning a number nobody can reproduce, and a tool can return a reproducible number without making its interpretation legible to a business user. Ask for evidence of each separately.
Evaluation Criteria: What a Verifiable AI Answer Must Show
Six criteria, each scored independently, turn a vague trust question into a comparison you can run against several vendors.
Criterion 1 — The answer is computed by a query engine, not composed as prose
The architectural difference decides whether verification is even possible. In one pattern, the AI layer translates your question into SQL or a semantic-layer query that executes against the database, and the number you see is that query's result. In the other, a language model composes text that may include numbers it inferred.
The first is verifiable by construction; the second requires separate checking of every figure. Snowflake's Cortex Analyst documentation illustrates the query-based pattern: it generates SQL against a semantic model and returns the interpreted question alongside the SQL statement. Ask each vendor which pattern their assistant uses, and do not accept "it uses AI" as an answer.
Criterion 2 — The generated SQL or query is visible to the user
Visibility of the query is what lets a non-technical user, or the analyst they escalate to, check the logic rather than the wording.
Two documented examples show what to look for. Snowflake's response format returns the interpreted question plus the SQL statement, as shown in the Cortex Analyst documentation. ThoughtSpot's Spotter documentation describes surfacing the search tokens used to construct an answer, highlighting changes made for follow-up questions, and letting users hover over formulas to see how they are calculated. Treat both as capabilities to confirm live in a demo, not as guarantees of accuracy.
Criterion 3 — The metric definition is inspectable
Many disputes are about definition, not arithmetic: revenue recognized when, which date field, cumulative versus point-in-time. A correct query against the wrong definition still produces a wrong answer.
Tableau Pulse's documentation states that behind every metric is a metric definition specifying core metadata such as the measure and aggregation, the time dimension, adjustable filters, and temporality — whether the value is cumulative over the period or a snapshot for the latest date. A tool that hides the definition makes verification impossible even when the SQL is right.
Criterion 4 — Curated, human-approved answers for high-stakes questions
The "verified answer" pattern pre-validates responses for recurring question categories, so a high-stakes question returns a reviewed result instead of a fresh interpretation.
Microsoft's Power BI documentation describes verified answers as responses a model author configures and validates, returned when a user's prompt matches a trigger phrase, with the matched phrase displayed so the user can see how the prompt was interpreted. Note the scope carefully: this covers matched questions, not every question, and verified answers do not work if the fields they use are hidden in the model.
Criterion 5 — The answer is traceable to governed data and permissions
Verification requires the answer to respect the same access controls and data definitions as the rest of your platform. An answer assembled from data the user should not see is not verifiable, it is a governance incident.
Snowflake documents that Cortex Analyst adheres to role-based access control for the SQL it generates and executes. On the modeling side, Power BI's AI data schema documentation describes letting authors select a focused subset of the model's fields for Copilot to prioritize, which reduces ambiguity — and notes that consumers cannot see the AI data schema set on the model, so the governance work happens upstream of the user.
Criterion 6 — An audit trail exists for the interaction
Ask specifically what gets logged. Microsoft's Fabric Data Agent audit logging documentation lists the fields in each record: timestamp, user identity, application and agent details, associated resources and metadata, and the user prompt or AI response, stored in the Microsoft 365 unified audit log.
The same page states an important limitation: these records capture user-facing interactions only and do not capture internal orchestration steps, intermediate reasoning, or backend queries the agent runs but does not return to the user. Prompt-and-response logging alone may therefore not reconstruct the computation. OWASP's logging guidance adds the baseline: logs must record "when, where, who and what" for each event, and the logging mechanisms and stored data must be protected from tampering and unauthorized access.
Red Flags and Deal-Breakers
The criteria above describe what good looks like. The signals below describe what should stop a purchase, and they are not the same severity: a red flag is a concern to investigate, while a deal-breaker is a reason to walk away.
Red flags
The tool shows a number with no way to see the query or the metric definition behind it.
"The AI said so" is the only evidence offered for a figure.
The answer cannot identify which data source or date range it used.
Audit logs capture only the chat text, not the query.
The vendor cannot demonstrate a reproducible check in a live demo.
Identical prompts return different numbers with no explanation of why.
Each of these undermines verifiability in the same way: it removes the artifact an independent person would need to check the result. A single red flag is worth a follow-up question; several together usually indicate the query-based architecture is absent.
Deal-breakers
Walk away, regardless of other merits, when any of the following holds for the answers that feed your consequential decisions:
No query or definition visibility.
No way to restrict the AI to governed semantic models.
No audit trail your compliance function will accept.
Inability to reproduce a number from source data during the trial.
These are not preferences to be traded against feature breadth. They are the conditions under which verification is structurally impossible, and no amount of interface polish compensates for their absence.
A note on "a second AI agreed with the first"
Two models agreeing is not verification. Both can share the same training-data biases and the same confabulation tendencies, and agreement is not evidence that either computed anything from your governed data.
NIST's profile is direct on this: GAI outputs may include confabulated logic or citations that purport to justify or explain the system's answer, which may further mislead humans into inappropriately trusting the system's output. A second model reviewing the first model's reasoning is another instance of that pattern, not an independent check. Verification means comparing the number against the governed data and the query that produced it.
How to Run a Trial Acceptance Test (Golden Set)
Before you trust an AI BI layer, test it the way you would test a new analyst: give it questions whose correct answers you already know, and watch how it shows its work. The method below is a suggested approach, not a report of observed results.
Build the golden set
Pick 15 to 30 questions spanning simple counts, filtered aggregates, time comparisons, and at least a few definition-sensitive metrics where reasonable people could disagree about the right answer.
Compute the correct answers independently, using analyst-written SQL or existing certified reports rather than the tool under test. Include questions the tool should refuse or flag because they fall outside the governed model — a question about a field nobody has modeled, or about data the test user is not permitted to see. Those negative cases are as informative as the positive ones.
Score each answer on reproducibility, not just correctness
For each question, record four things: whether the number matched, whether the SQL or definition was visible, whether the source and date range were identifiable, and whether an independent analyst could reproduce it.
A right number with no visible logic is a weaker pass than a right number with a checkable query. Score the two dimensions separately, because a tool that guesses correctly on your golden set will eventually guess incorrectly on a question you did not anticipate — and only the visible logic tells you which happened.
Test the failure modes deliberately
Correct answers on clean questions prove little. Add questions designed to break the tool: ambiguous prompts, business terms that map to two or three fields, and requests for data the user is not permitted to see. Watch whether it asks for clarification, states its interpretation, or guesses silently. Documented behavior gives you something concrete to look for — Power BI's verified answers display the matched trigger phrase, and Snowflake's Cortex Analyst returns the interpreted question alongside the SQL. If your candidate cannot show how it read the prompt, you cannot tell a correct answer from a lucky one.
Using the Criteria to Decide
The six criteria and the red flags are inputs to a decision, not a scorecard to total up. What matters is which criteria your highest-consequence use cases depend on, and whether the vendor can demonstrate those capabilities on your data rather than on a prepared demo.
Weight by consequence, not by feature count
A tool with strong query visibility but thin audit logging can be a reasonable fit for exploratory analytics and a poor one for financial reporting. Return to the consequence tiers from your needs assessment and ask which criteria each tier actually requires. A tier that feeds board decks or regulatory filings needs query visibility, definition visibility and an audit trail together; a tier used for internal exploration may only need the first two. Weighting by consequence keeps a long feature list from outvoting a missing capability where it counts.
Require demonstrated evidence in the demo
Ask the vendor to reproduce a number live: pose a question from your golden set, show the SQL or metric definition behind the answer, and then pull the audit record for that same interaction. If any step has to happen "in a follow-up session" or on a different dataset, treat it as unproven. Vendor-reported accuracy and performance figures are claims to validate in your own environment, not evidence of verifiability — the same standard this guide applies to every other number.
Phase the rollout
Start with governed, lower-stakes questions where a wrong answer is cheap to catch. Expand scope only as the golden set passes consistently and reviewers stop finding definition mismatches. Revisit the criteria whenever the semantic model, the underlying data sources or the AI configuration changes, because a capability demonstrated against last quarter's model says nothing about this quarter's.
A Practical Acceptance Checklist
Carry this into evaluation and score each candidate against it. Items marked with a source are documented capabilities in at least one product; confirm them in your own demo rather than assuming them.
For each high-stakes question, the tool shows the SQL or semantic-layer query that produced the number.
The metric definition — measure and aggregation, time dimension, filters, temporality — is visible to the user, as Tableau Pulse documents for its metric definitions.
The answer identifies its data source and date range.
The AI is restricted to governed semantic models and respects existing access controls, as Snowflake documents for Cortex Analyst's role-based access control.
Curated verified answers exist for recurring high-stakes questions, with the matched phrase shown to the user.
Audit records capture timestamp, user, prompt and response, and — where available — the query itself.
The golden set reproduces independently computed answers, and an analyst can re-run the logic.
The tool asks for clarification or flags ambiguity rather than silently guessing.
A second AI's agreement is not accepted as verification.
Frequently Asked Questions
Short answers to the questions buyers raise most often during evaluation.
How do I tell whether an AI answer was computed from governed data or fabricated?
Look for the query or semantic-layer logic, the source and the definition. If the tool cannot show these, treat the number as unverified no matter how confident it sounds. NIST describes confabulation as a natural result of how generative models produce output, so fluency is not evidence of computation.
What evidence should accompany a single AI-generated number so an auditor can verify it?
The query or metric definition, the data source and date range, the user and timestamp, and a way to reproduce the result. Ask specifically for query-level traceability: Microsoft documents that Copilot Interaction audit records capture user-facing prompts and responses only, not backend queries the agent runs without returning them.
Which BI tools let a non-technical user see the SQL or metric definition behind an answer?
Documented examples include Snowflake Cortex Analyst, which returns the interpreted question and SQL; ThoughtSpot Spotter, which surfaces the search tokens used to build an answer and lets users hover over formulas; Tableau Pulse, which exposes metric definitions; and Power BI, which offers verified answers and AI data schemas. Treat these as capabilities to confirm in a demo, not as endorsements or accuracy guarantees.
What should I put in a trial acceptance test before trusting an AI BI layer?
A golden set of 15–30 questions with independently computed answers, scored on reproducibility and visibility of logic, plus deliberate tests of ambiguity and permission boundaries. A right number with no visible query is a weaker pass than a right number you can re-run.
What audit-log fields should finance or compliance ask for?
Timestamp, user identity, application and agent details, the prompt, the response, and the query where available. OWASP's logging guidance holds that application logs must record "when, where, who and what" for each event and be protected from tampering. Ask explicitly how the gap between user-facing logs and backend query logs is closed.
Is a second AI agreeing with the first a valid verification method?
No. Agreement between models is not evidence of computation from governed data; both can share the same training-data biases and confabulation tendencies. NIST notes that GAI can produce confabulated logic or citations that appear to justify an incorrect answer. Verification means checking against the governed data and the query.