
Revenue Doubled While Contract Value Grew 6%: AI Buying Has Become a Series of Short Proofs
Palantir's Q3 2026 revenue grew 95.9% while total contract value rose 6%. Why AI buyers now fund a chain of bounded, falsifiable proofs instead of multi-year commitments, and the controls that keep those proofs from becoming platform drift.
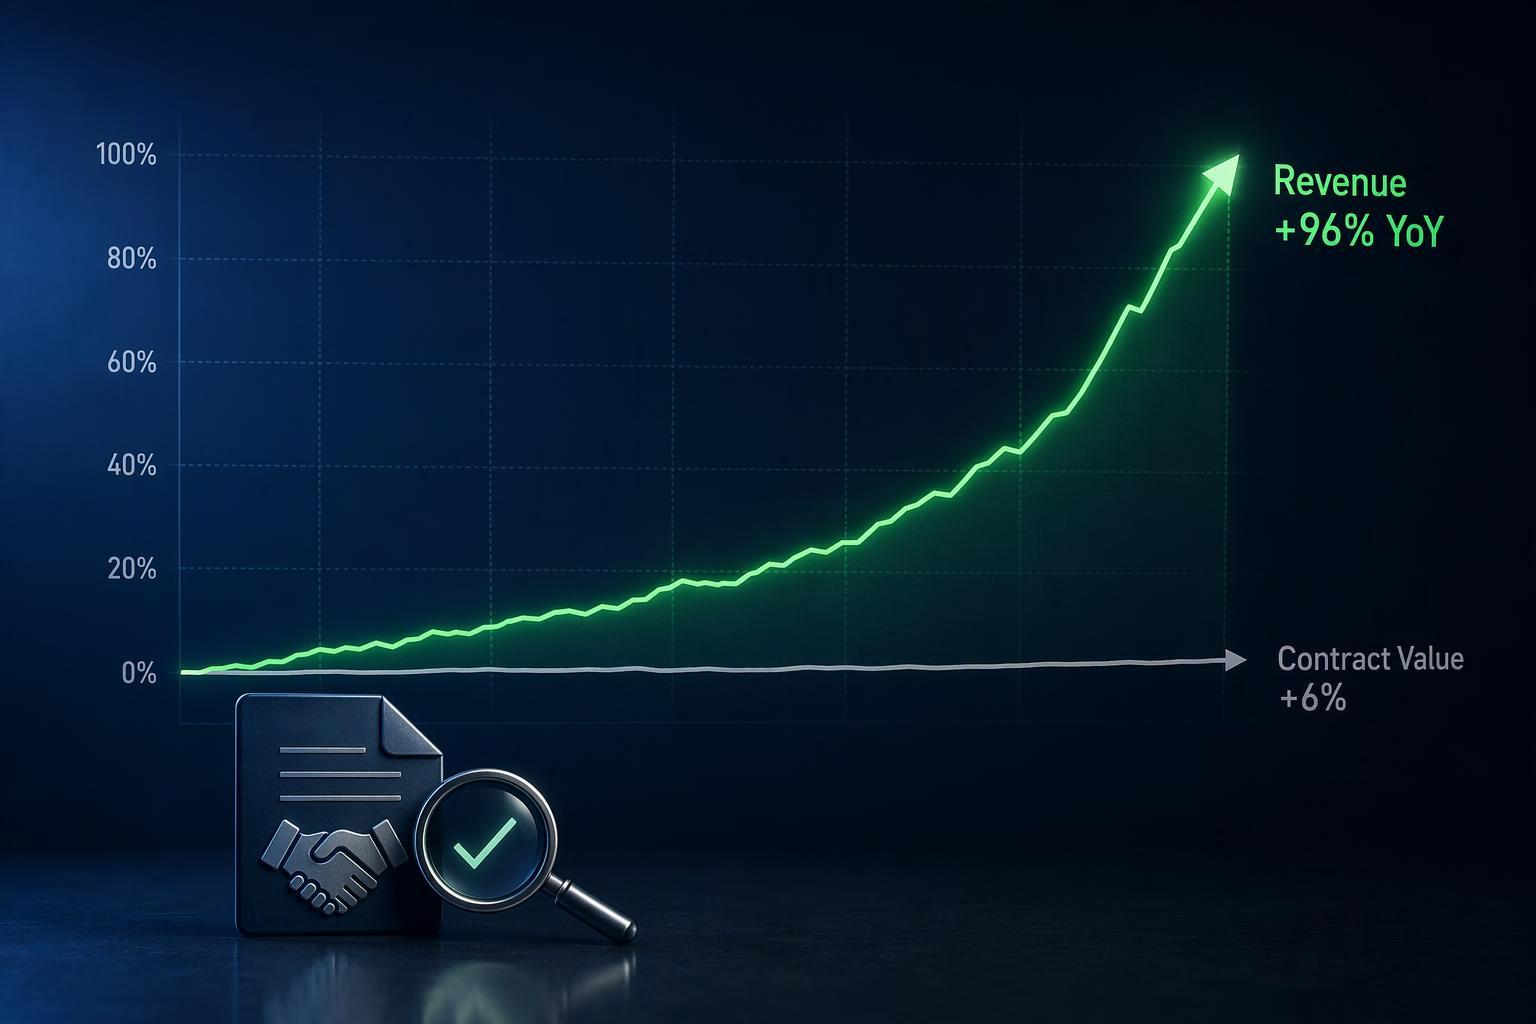
Palantir's third-quarter 2026 report contains a contrast worth pausing on. Revenue reached $2.313 billion, up 95.9% year over year, the fastest growth in the company's public history. Total contract value closed in the same quarter rose 6%, to $2.918 billion, after 49% growth the quarter before. U.S. commercial remaining deal value grew 4% sequentially. Remaining performance obligations were flat at $4.9 billion.
That gap does not measure a collapse in demand, and it does not prove durable expansion either. It measures something narrower and more useful: the unit of commitment is shrinking. Buyers are signing shorter, smaller, more conditional agreements, and vendors are recognizing revenue from work delivered against contracts signed earlier.
For CTOs, data leaders, procurement teams and finance organizations evaluating AI platforms, the practical consequence is that a purchase decision is no longer a single event. It is a sequence of bounded tests, each of which has to produce evidence before the next one is funded. This article defines what a short proof is, shows how buyer behavior and finance scrutiny produced the shift, and sets out the controls that keep a chain of proofs from turning into unaccounted platform drift.
What the Revenue-to-Contract-Value Gap Actually Measures
Revenue and total contract value answer different questions, and the difference explains most of the headline.
Revenue is recognized as work is delivered. TCV, as Palantir defines it in its Q3 2026 press release, is "the total potential lifetime value of contracts entered into with, or awarded by, our customers at the time of contract execution." The same disclosure states that TCV presumes the exercise of all contract options available to customers and no termination of contracts, while noting that "the majority of our contracts are subject to termination provisions, including for convenience." Annual contract value is derived differently again: total value of contracts closed in the period divided by the dollar-weighted average contract duration of those same contracts.
Three mechanics follow from those definitions.
First, revenue in a quarter reflects delivery against the installed base of earlier contracts. A company can post record revenue while new bookings decelerate, because the two figures describe different cohorts of work. Palantir's revenue growth accelerated for four consecutive quarters even as TCV growth fell from 49% to 6%, as Earnings Whispers summarized the quarter.
Second, duration sits in the denominator of ACV and in the lifetime assumption of TCV. When several eight-figure deals carry shorter-than-usual terms, the same number of deals and the same consumption can produce a materially lower TCV. Management said on the Q3 2026 earnings call that it signed multiple eight-figure deals "shorter in duration than usual" as customers adopted initial Sovereign AI capabilities, and that it expects duration and size to increase over time. That is a management expectation, not a demonstrated trend.
Third, TCV is a gross potential figure. Because most contracts can be terminated for convenience, TCV overstates committed spend relative to a backlog measure that excludes cancellable amounts. Palantir's own disclosure separates TCV from remaining performance obligations, which represent non-cancelable contracted revenue not yet recognized.
What the gap cannot tell you: it is not evidence that AI demand is falling, since revenue, customer count (686 U.S. commercial customers, up 29% year over year) and net dollar retention (165%, up from 157%) all moved the other way. Nor is it evidence that expansion is durable, since the forward indicators that would show that — bookings, backlog, duration — all cooled in the same period. Read narrowly, the 96%-versus-6% contrast says the commitment buyers are willing to sign has become smaller and shorter than the work they are willing to consume.
Why AI Buyers Stopped Buying Big
The buyer-side data explains why. Three independent surveys point at the same structural change.
G2's 2026 Buyer Behavior Report, based on a survey of more than 1,000 B2B software buyers fielded in June 2026. The first bar is all respondents; the second and third compare buyers whose CFO reversed an already-approved purchase in the last 12 months with those who did not experience a late-stage veto. G2 does not report the base sizes for these subgroups, so the subgroup percentages should be read as directional.
G2's 2026 Buyer Behavior Report, based on a survey of more than 1,000 B2B software buyers, found that 70% say the pace of AI innovation is pushing them toward shorter contracts, and 29% want terms under 12 months. The same research found that 49% of buyers report their CFO reversed a deal the buying team had already approved in the last 12 months. Among organizations with a dedicated token or LLM budget, that figure rises to 54%, against 29% where no such budget exists. Three in four buyers now expect positive ROI within six months of signing.
The finance veto is not arbitrary. Token and consumption pricing make the total cost of an AI deployment depend on usage patterns the buyer cannot fully predict at signature. G2 reports that 80% of buyers now give technical teams a token or LLM usage budget, with 37% managing it centrally and 47% at department level. When the invoice is variable, a multi-year commitment transfers model and usage risk to the buyer.
Forrester's State of Business Buying, 2026, drawing on a survey of nearly 18,000 global business buyers, found that buying groups for purchases including genAI features roughly double in size — 14 members versus seven for purchases without them — and that more than 60% of buyers purchase some form of trial, from limited pilots to paid sandbox environments. Procurement now acts as decision-maker in 53% of the average buying cycle. Forrester also notes that trial participation does not guarantee conversion: just over a third of buyers planned to convert to a fully paid version with the same provider.
On the sell side, a BCG survey of chief revenue officers found that 51% report greater demand for customized proof of value, with buyers expecting that proof to reflect their own data, processes and environments. BCG's analysis describes appetite for "open-ended strategy-first selling" fading in favor of "bounded, testable ways to move from discussion to execution."
The synthesis is straightforward. More approvers, each with a veto. A cost structure the buyer cannot forecast at signature. A trial norm that does not reliably convert. The purchase decision has moved later and become incremental, because committing early and large now carries risks the buying group cannot price.
A Working Definition of a Short Proof
A short proof is a bounded test designed to be falsifiable, run in the buyer's environment, whose result determines whether the next tranche of spend is released. It is defined by five fields, each of which must be written down before the run begins.
Scope. One workflow, one dataset boundary, one decision. Not "evaluate the platform," but "reduce the elapsed time to produce the monthly close reconciliation from nine days to four, using the general ledger and subledger extracts already in the warehouse." A scope that spans multiple workflows cannot fail cleanly, because a partial result admits too many interpretations.
Owner. A named business owner who accepts the evidence and owns the decision it informs. An IT sponsor can fund a proof; only a business owner can certify that the outcome matters. Where the owner is unclear, the proof will pass technically and stall commercially.
Duration. A fixed window with a checkpoint before any expansion. The window should be set by the decision the proof informs, not by the vendor's implementation timeline. The Australian Digital Transformation Agency's guidance on AI proof-of-concept procurement recommends short timelines of three to six months with evaluation gates for scaling.
Accepted evidence. The specific metric and threshold, agreed in advance, measured in the buyer's environment with the buyer's data. "Improved analyst productivity" is not evidence. "Median time to answer the ten pre-agreed questions falls below two minutes, measured on the production dataset, verified by the analytics team lead" is.
Failure conditions. The result that ends the proof without proceeding. This field is the one most often omitted, and it is the one that makes the exercise a proof rather than a sales motion. If no result would stop the project, the project has already been decided.
A short proof differs from a demo and from a conventional pilot. A demo shows that the technology works; it says nothing about whether it works on the buyer's data, under the buyer's governance, at the buyer's cost point. BCG makes the distinction directly: "a successful demo may show that the technology works without creating conviction that the product will work in the customer's environment." A pilot is often scoped to succeed — broad enough to generate enthusiasm, vague enough that no single result can end it. A short proof is scoped to fail cleanly if the premise is wrong.
How Procurement, Pricing and Internal Approval Change
Proof-based buying changes the contract on both sides of the table.
The DTA's PoC guidance is a useful public-sector reference because it specifies the terms that make a bounded test enforceable rather than aspirational. It recommends a concise statement of objectives covering the problem, expected insights, duration and exit criteria; staged contracts with clear deliverables and evaluation gates; IP terms specified upfront so the buyer retains rights to adapt or scale what the proof produces; data access and sovereignty requirements written into procurement conditions; open data formats and APIs as mandatory criteria; and export of model artefacts and documentation so the buyer can transition, replace or re-host after the proof. It also recommends linking payments to evidence of learning outcomes.
Those terms translate directly to commercial buyers. A staged contract with an evaluation gate converts a proof from a courtesy into a decision point. A short initial term with a defined exit or pivot preserves the buyer's option while the evidence accumulates. Payment tied to learning outcomes aligns the vendor's incentive with the buyer's need to know, not with the buyer's need to be impressed.
On the vendor side, the pricing structure has to separate the cost of the proof from the cost of scale. A proof priced like a small production deployment either loses money or discourages the buyer; a proof priced at zero signals that the vendor expects to recover the cost through lock-in rather than through demonstrated value. ICONIQ's 2026 State of Go-to-Market report, based on a January 2026 survey of GTM executives at more than 150 B2B software companies, found that free trial and proof-of-concept motions converted at roughly 50% in 2026, against 25–35% for SQL and demo paths. The same report notes that companies offer different levels of PoC support by contract value: dedicated solutions architects are far more common at ACVs above $100K than below $50K. The report's conclusion is that PoCs convert when treated as a disciplined operating motion with preparation before the pilot and execution alongside the customer during it — not as a trial left to run on its own.
The CFO's role deserves explicit treatment, because the finance veto is where most proof chains break. A proof that produces a defensible number — a measured result, a cost-to-serve estimate at production scale, and a traceable line from spend to outcome — is the artifact that survives a late-stage review. G2's research puts the requirement plainly: the deal is won when the buyer can defend the number, not when the user says yes.
Keeping a Chain of Proofs From Becoming Drift
The central risk of incremental buying is that many small wins never compose into a platform decision. Each proof passes, each renewal is signed, and three years later the organization has fragmented tooling, duplicated data movement, three semantic definitions of the same customer, and a cost base nobody owns.
Four controls prevent that.
A standing register of active proofs. One list, maintained by a named owner, recording for each proof: the business owner, the evidence threshold, the decision date, the platform capability under test, and the reuse it creates. A proof that appears on no register is a proof nobody will remember approving.
A reuse rule. Every proof must name the platform capability it tests and the asset it leaves behind — a governed dataset, a semantic definition, a pipeline pattern, a permission model. Proofs that leave nothing reusable are consumption, not evaluation.
A quarterly composition review. The question is not whether each proof passed but whether the accumulated set points to one architecture or several. If four proofs in four business units produced four separate data copies and four separate access models, the organization is not converging on a platform; it is buying four products.
A stop rule for technical passes with no production path. Some proofs will meet their metric and still have no route to production, because the data owner will not grant standing access, or the cost at scale exceeds the budget line, or no team will own the workflow after the pilot team disbands. Those proofs should be closed and recorded as closed. Leaving them open consumes attention and creates the impression of progress.
Data-platform specifics matter here more than in most categories, because architecture decisions made during a proof are difficult to reverse. A proof that leaves data in open formats, in the buyer's own object storage, and avoids re-ingestion preserves the option to consolidate later. A proof that copies data into a proprietary store, builds transformations against vendor-specific semantics, and requires re-ingestion to move forecloses that option. The DTA guidance treats this as a procurement requirement rather than a technical preference: open formats, exportable artefacts and documented exit paths should be conditions of the proof, not aspirations for the production contract.
The practical test for a chain of proofs is whether each one leaves the organization more able to consolidate than the one before it. If the answer is no, the chain is drift with better record-keeping.
What Evidence Should Gate the Next Step
Before releasing the next tranche of spend, run the proof against a fixed acceptance checklist. Each item should be answerable with a document, not a recollection.
The pre-agreed metric was met, in the buyer's environment, with the buyer's data. If the metric moved during the run, the original threshold governs; a revised threshold is a new proof.
The business owner has accepted the evidence in writing. Not the IT sponsor, not the account team — the person who owns the workflow and will own the production system.
A cost-to-serve estimate at production scale exists. For AI workloads this must include token or compute consumption at expected volume, not only licence cost. A proof run on a narrow data slice says little about the unit economics of the full dataset.
A production owner and support model are named. The team that will operate the system, the support tier it will receive, and the escalation path are decided before the next tranche is released.
An exit or portability path is documented. Export rights, data formats, artefact ownership and the effort required to move are written down.
The next step is larger but still bounded. Expansion should be a defined increment with its own evidence threshold, not an open-ended production commitment.
Designing proofs that are cheap to run is a discipline in itself. Narrow data slices, fixed evaluation windows and thresholds registered before the run all reduce cost and increase evidential value. The DTA guidance frames the same principle as proportionality: a proof should not commit long-term funding before evidence of value exists.
Three failure modes invalidate a proof after the fact, and all three are common.
Moving the metric. If the original threshold proves unreachable, the honest response is to record the miss and design a new proof. Redefining success mid-run converts evidence into advocacy.
Widening the scope mid-run. Scope creep during a proof usually arrives as a reasonable request to "also check" an adjacent workflow. It destroys the falsifiability that made the proof worth running.
Accepting a vendor-run demonstration as evidence. A demonstration in a vendor environment, on curated data, with the vendor operating the system, tests the vendor's capability to demonstrate. It does not test the buyer's capability to operate. BCG notes that production exposes data, integration, governance and process constraints that a pilot can sidestep; a demonstration sidesteps all of them.
Forecasting, Sales Capacity and Retention Under Proof-Based Growth
When growth comes from more proofs won rather than larger contracts, the commercial model has to be rebuilt around proof units.
ICONIQ's 2026 State of Go-to-Market, from a January 2026 survey of GTM executives at more than 150 B2B software companies. Conversion is the share of free-trial and proof-of-concept motions reaching a paid version; the SQL/demo range spans two separate funnel paths. ICONIQ reports these as survey averages across respondents, not as outcomes for any single vendor or deal.
Forecasting. Pipeline should be modeled in proofs, with stage-specific conversion rates, rather than in contract value alone. Revenue timing then depends on the lag between a passed proof and a production commitment, not on the signature date of the initial agreement. ICONIQ's data illustrates the shape of the change: sales cycles shortened by roughly six weeks while sub-one-year contracts rose, with the share of new-logo subscriptions under one year climbing across the 2023–2026 survey waves. Faster signature and smaller commitment are two sides of the same buyer preference.
Sales capacity. More proofs per dollar of revenue means more delivery and solutions-engineering load per deal. ICONIQ's PoC support data shows the cost curve: dedicated solutions architects are the norm at higher ACVs and rare at lower ones, which means a strategy built on many small proofs either accepts lower support levels or carries a higher delivery cost per dollar booked. The practical response is repeatable proof kits — pre-built environments, standard evaluation harnesses, documented data requirements — that reduce the marginal cost of the next proof without reducing its rigor.
Retention. A short proof converts to a renewal only if evidence accumulates across proofs. Palantir's reported figures show what the expansion path can look like: net dollar retention of 165%, and pilot-to-contract conversions including a $1 million pilot that expanded to a $15 million ACV deal within the same quarter, and a $2.5 million pilot that converted to an $11.5 million ACV deal. Those are vendor-reported examples from the Q3 2026 earnings call, not a benchmark, and a buyer or vendor should treat them as illustrations of a possible path rather than an expected outcome.
The honest limit on this section is the same one that applies to Palantir's own guidance. Management expects deal duration and size to grow over time as customers move from initial adoption to broader deployment. That expectation is plausible and consistent with the expansion examples, but it is not yet a demonstrated trend. A vendor building a forecast on the assumption that short proofs reliably lengthen into multi-year contracts is building on an expectation. A buyer building a platform strategy on the assumption that short proofs reliably compose into one architecture is making the same bet from the other side.
Conclusion
The 96%-versus-6% contrast is best read as a change in the unit of purchase, not a verdict on demand. Revenue grew because work was delivered against contracts already signed. Contract value grew slowly because the contracts being signed are shorter, more conditional and more often subject to termination. Buyers are purchasing evidence in installments.
That pattern rewards vendors that can produce short, falsifiable, cheap proofs and then compose them into a coherent platform story. It penalizes vendors that need a large commitment before they can demonstrate value, and it penalizes buyers who run proofs without a register, a reuse rule or a stop rule, because a chain of unconnected wins is how organizations end up with fragmented tooling and unowned cost.
The first action is small and specific. Before approving the next AI purchase, write down the five fields of the proof: the single workflow and dataset boundary in scope, the named business owner who will accept the evidence, the bounded duration with its checkpoint, the metric and threshold agreed in advance and measured in your environment, and the result that would end the proof without proceeding. If any field cannot be completed, the proof is not ready to fund.
FAQ
Does the contract value slowdown mean AI demand is falling?
No. Palantir's revenue grew 95.9% in the same quarter, U.S. commercial customer count rose 29% year over year, and net dollar retention increased to 165%. TCV is a gross potential figure that presumes all contract options are exercised and no contracts are terminated, while most of the company's contracts carry termination-for-convenience provisions. A period of shorter deal durations depresses TCV mechanically even when deal count and consumption rise.
How long should a short proof run?
The duration should be set by the decision the proof informs, with a checkpoint before any expansion. Public-sector guidance on AI proof-of-concept procurement recommends three to six months with evaluation gates for scaling. A proof that runs longer than the decision it serves is usually accumulating scope rather than evidence.
Do short proofs increase total cost?
They can. More proofs per dollar of revenue raises delivery and solutions-engineering load, and each proof carries setup, data preparation and evaluation cost. That is why reuse matters: standard proof kits, shared evaluation harnesses and proofs that leave behind governed datasets and semantic definitions reduce the marginal cost of the next test. A chain of proofs that produces no reusable assets is an expensive way to buy the same information repeatedly.
How do we prevent vendor lock-in during a chain of proofs?
Specify the exit terms before the first proof begins: open data formats, export of model artefacts and documentation, buyer retention of IP or a perpetual licence for deliverables, and a documented path to transition, replace or re-host. The DTA's PoC procurement guidance specifies open data formats and interoperability as mandatory criteria, while listing IP terms, export of model artefacts and transition planning as practical actions to require upfront; the same logic applies to commercial buyers.
Does this pattern apply outside AI software?
It is most pronounced where consumption costs are variable and the underlying technology changes quickly, because both make multi-year commitments hard to defend to a finance reviewer. Traditional seat-based software with predictable usage has less exposure. The closer a purchase sits to token or compute consumption, the more the buying process resembles a series of short proofs.
find out more
https://www.singdata.com/documents/data_security
https://singdata.com/trending/medallion-architecture-genai-data-contracts-future-trends/