
How Singdata Prevents AI SQL Hallucinations: A Validation-First Guide
A validation-first guide to AI SQL hallucination prevention: the layers between a business question and an executed query, what Singdata's row-level and masking documentation actually specifies, and a pilot checklist that scores validation outcomes rather than plausible-looking numbers.
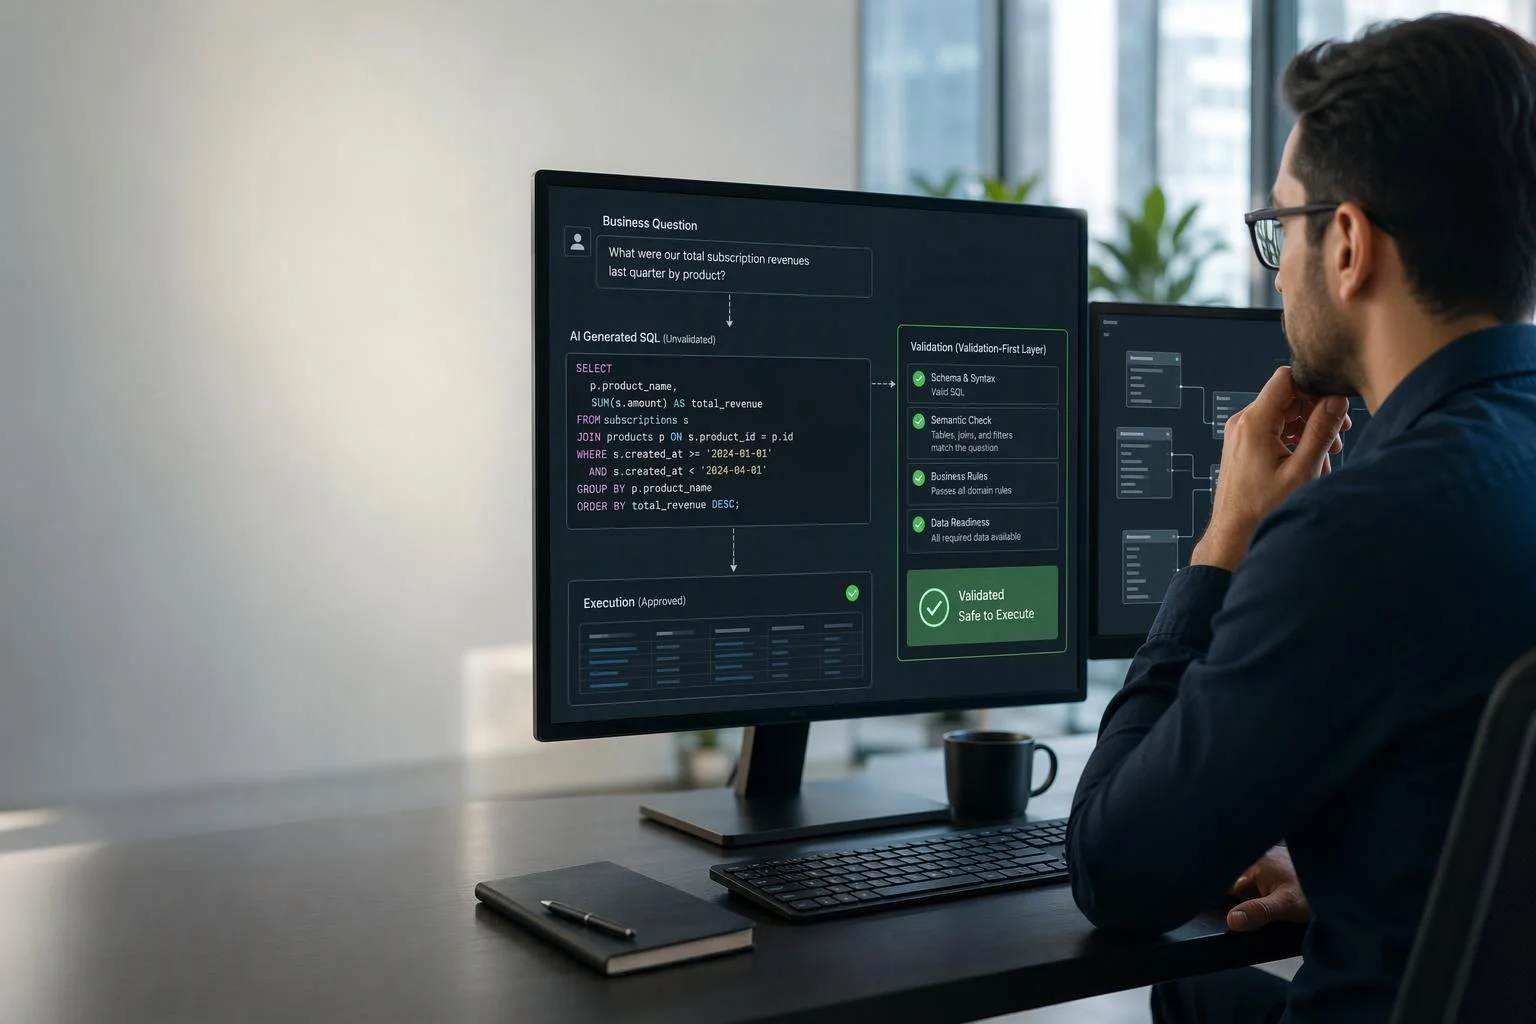
A hallucinated query is not usually broken SQL. It parses, it runs, and it returns a number. What it does not do is answer the question that was asked. That gap — between a statement the engine accepts and a result the business can act on — is the failure mode this guide addresses, and it is the one that erodes trust fastest, because nothing in the stack raises an error.
If you are an IT decision-maker or data lead evaluating natural-language analytics, the useful question is not whether a vendor's model is good. It is where, between a business question and an executed query, the platform places checks that can stop a wrong query before it runs — and how you would prove those checks work in your own environment. This guide walks that path layer by layer, describes which controls Singdata's documentation actually specifies, and gives you a pilot protocol that tests validation outcomes rather than whether a returned figure looks plausible. Vendor claims, including Singdata's, are treated here as things to validate, not accept.
What an AI SQL Hallucination Actually Is
The canonical distinction comes from Brass and Goldberg, whose taxonomy separates a syntactic error — a character string that is not a valid query — from a semantic error, where a legal query is entered but does not produce the intended results. Their central finding is that database management systems execute such queries without any warning. Current text-to-SQL evaluation research restates the same two-predicate test: a query must be both syntactically valid against the database and semantically faithful to the question's intent (ROSE, ACL 2026).
The engine enforces the first predicate and is silent on the second. It knows whether a column exists and whether types align. It does not know whether "revenue" in your finance team's sense means gross or net of refunds, whether the quarter is calendar or fiscal, or whether the row grain should be order or order line.
Consider an illustrative inference, not observed data: a request for "revenue by region last quarter" can be written as a clean join and sum that passes every syntax and schema check, yet return a different total depending on whether refunds are netted and whether the grain is order or order line. Fan-out from a one-to-many join inflates a total without changing a character of the SQL. The query is valid. The answer is wrong.
The research record shows how hard the semantic axis is to measure, let alone automate. On BIRD, a benchmark built from 95 databases totaling 33.4 GB across 37 professional domains, GPT-4 reached 54.89% execution accuracy against a human result of 92.96% (Li et al., NeurIPS 2023). Execution accuracy itself is a noisy yardstick: an analysis of annotation errors found rates of 52.8% in BIRD Mini-Dev and 66.1% in Spider 2.0-Snow, and re-evaluating five leading agents on corrected data moved execution accuracy by −2% to 19% in absolute terms and shifted rankings by up to three places (Jin et al., CIDR '26). FLEX, a metric designed to align more closely with expert judgment, reports Cohen's kappa of 87.04 against human evaluation versus 62.00 for execution accuracy (Kim et al., NAACL 2025).
The practical consequence: syntax and execution checks catch almost none of the failures that damage trust in a business setting. A pipeline that only asks "did it run?" is measuring the axis that was never in doubt.
The Layers Between a Question and an Executed Query
A production pipeline is a sequence of gates, and each one assumes the previous one closed. The six-layer chain below is a design pattern documented in a survey of production text-to-SQL pipelines rather than a standard's text, but it reflects how these systems are actually assembled (Validation-Gates Survey).
Intent resolution settles what the question asks: entity, grain, scope, time window, filters, exclusions, and expected output shape. It catches questions that map to more than one valid query and should be clarified rather than generated. It cannot catch a question that is unambiguous but rests on a contested definition — that belongs to the next layer.
Metric and definition resolution maps the business term to a governed definition: numerator, denominator, aggregation, and treatment of nulls, duplicates, refunds, and late-arriving records. It catches the case where a plausible column name stands in for a business concept. It cannot repair a definition that is itself wrong; a versioned but incorrect metric will be applied faithfully and wrongly.
Schema and catalog grounding binds identifiers to objects that exist in the live catalog. It catches hallucinated columns and unauthorized tables. It cannot catch a real column used for the wrong purpose.
Statement validation applies a statement-type allowlist with default deny, AST structural checks, and a compile or dry-run gate. It catches writes where reads were expected and references to objects outside the approved set. A dry run confirms the statement compiles; it says nothing about whether the result is meaningful.
Policy injection mechanically adds tenant, row, and date predicates into the statement's AST. It catches missing access predicates. It cannot catch a policy that is itself misconfigured.
Database-level enforcement applies read-only grants and native row-level security as the final backstop. It catches anything the earlier layers missed on the access axis. It has no view of semantic correctness at all.
The so-what is asymmetric. Drop intent or metric resolution and you keep a fast system that confidently answers the wrong question — the failure mode most likely to reach an executive dashboard. Drop policy injection or database enforcement and you have a correctness problem plus a data-exposure problem. The layers are cheap to describe and expensive to skip, which is why the order matters: generation belongs last, after the question and the definition are settled.
Where Singdata's Platform Fits
Singdata's public documentation describes specific governance controls. It is worth being precise about what those pages state and what they do not.
The row-level permissions documentation describes filter rules that restrict users to rows meeting specified conditions. Once a rule takes effect, queries generated by the Agent automatically include the corresponding filter conditions, transparently to the user. The documented example is regional: a North China user and a South China user asking the same question each see only their own region's data. The page also states that a user can be covered by multiple permission rules and that the combined scope should be verified against expectations — a configuration caution, not an automatic guarantee.
The dynamic masking guide describes column-level security through masking functions bound to columns, evaluated at runtime against current_user() and current_roles(). The system stores original data and executes the masking function during access. The page is explicit about privilege behavior: a querying user needs SELECT on the table and USE FUNCTION on every masking function the query executes, and if that privilege is missing on any required function, the entire query fails with a NoPermission error rather than returning NULL or a masked value. It also states a limit: only one masking policy can be bound to a single column, so multiple rules must be expressed as conditional logic inside one function.
Those two documents describe controls and their configuration. They do not report a measured hallucination rate, an accuracy figure, or a benchmark result for Agent-generated queries, and nothing here should be read as claiming one. Singdata also publishes material on metric resolution and semantic validation that frames validation as a checkpoint between generation and execution with allow, deny, warn, and repair outcomes. Treat that as the vendor's stated design position — a description of intended architecture that a buyer should confirm operates as described in a pilot, not as evidence that it does.
The honest summary: the documentation establishes that row-level filtering and column masking exist, how they are configured, and what happens when privileges are missing. It does not establish how often the platform's semantic checks prevent a wrong answer. That is a question for your test set.
Prompt Instructions vs. a Pre-Execution Validation Gate
Many products ship a system prompt that instructs the model to query only approved tables, avoid DML, and say "I don't know" when the schema cannot answer the question. These instructions are real and sometimes useful. They are also not access control. A prompt-level guardrail is honored by a model with no schema-wide privileges and bypassed by anything that gets a foothold in the retrieved context. If a sentence in a system prompt is your only defense against an unauthorized query, you do not have that defense.
The distinction that matters is between a hint and an enforced gate. Four questions separate them, and none requires access to the vendor's source code — each can be answered by watching behavior in a pilot.
Does the control survive a hostile or ambiguous question? Ask something designed to route around the instruction: a request phrased as an exception, a question with two plausible readings, a prompt injection embedded in a document the agent retrieves. A prompt instruction degrades under pressure; an enforced gate produces the same outcome regardless of phrasing.
Does it produce a deny or repair outcome before execution? The observable event is a query that never runs, or one that is rewritten against a governed definition before it runs. If the only outcomes you can observe are "ran" and "errored," you are watching the database, not a validation layer.
Is it evaluated against the catalog rather than the model's memory? A check that compares generated identifiers to the live catalog catches hallucinated columns. A check that trusts the model's recollection of the schema does not.
Can it be observed in logs? A gate that leaves no record of its decision cannot be audited, tuned, or defended to a regulator. The log entry should show the question, the resolved definition, the validation outcome, and what was returned.
A useful test: submit the same adversarial question twice, once with a system prompt that permits the behavior and once without. A prompt-level control changes its answer. An enforced gate does not.
Permissions When a Business User Queries Through an Agent
When the consumer is an AI agent rather than a BI tool, the permission model does not change in principle but the enforcement point does. The agent writes a query the user never sees, so the control has to be compiled into the statement or applied by the engine — not applied as a filter to a result set after the fact.
Singdata's row-level documentation describes the first approach: rules are configured against a table and filter field, scoped to users, and the Agent's generated queries automatically include the filter conditions. Enforcement happens as the query is built, which is the property that matters. A result-set filter applied afterward still executes a query over the full table; if the query is logged, cached, or joined downstream, the wider row set has already been touched.
Column masking behaves differently and the difference is operationally important. In Singdata's documented model, masking functions execute at read time and evaluate the querying user's identity and roles. The privilege requirement is strict: missing USE FUNCTION on any required masking function fails the whole query with NoPermission. That is a deliberate fail-closed design — you get an error, not a silently unmasked column — but it means provisioning must grant function privileges alongside table SELECT, and a role that can read a table but not its masking functions will see failed queries rather than masked data.
Snowflake's documentation describes comparable runtime behavior for comparison. Column masking policies are applied at query runtime to the column at every location it appears, and depending on policy conditions, execution context, and role hierarchy, an operator may see plain text, partial masking, or full masking (Snowflake column-level security). Row access policies are likewise evaluated at query runtime against the role of the operator executing the query (Snowflake row access policies). The shared principle across both platforms: policy is evaluated when the query runs, against the identity of the person on whose behalf it runs — which for an agent means the requesting user, not the service account.
Two configuration details deserve a test in any pilot. First, a user can be covered by multiple permission rules, and the combined scope is what the user actually sees; Singdata's page recommends verifying that the combined data scope meets expectations. Second, masking rules that depend on conditional logic inside a single function must be reviewed as code, because only one policy binds per column and the branching is where errors hide.
What Evidence to Request From a Vendor
The following is a buyer's recommendation, not a published standard. Each artifact below is something a vendor can produce in a scoped pilot, and each proves less than it appears to.
Query explanations tied to the metric used. Ask the system to show, for a given answer, which governed definition it resolved to, which grain it applied, and which filters it injected. This proves the platform has a resolution step and can expose it. It does not prove the definition is correct for your business — only your metric owners can confirm that.
Audit logs of who asked what and what was returned. Ask for a log entry covering question, resolved definition, validation outcome, executed statement, and returned result. This proves observability exists and is usable for investigation. It does not prove the log is complete or tamper-evident; ask how long entries are retained and who can alter them.
Demonstrated validation-gate behavior on adversarial questions. Prepare your own hostile set: ambiguous questions, unanswerable questions, requests that imply a forbidden table, questions with a plausible but wrong grain. This proves the gate produces deny or repair outcomes on cases you designed. It does not prove coverage of cases you did not think of, which is why the set should grow from production incidents.
Real abstention or denial examples. Ask to see a case where the system declined to answer and stated why. This proves abstention is a designed outcome rather than an error path. It does not prove the abstention rate is acceptable for your users; a system that declines too often is safe and useless.
One artifact worth requesting that vendors rarely volunteer: a statement of what the platform does not validate. A vendor who can name the boundary of their checks is more useful than one who claims none exists.
A Pilot Acceptance Checklist
The checklist below is the author's protocol for a scoped pilot. It is designed so that a passing result means the validation layer behaved correctly, not that a number looked reasonable.
Build a known-answer test set. For each question, record the established correct metric, the grain, and the permitted row set before the pilot starts. Twenty to thirty questions drawn from real requests is enough to start. Include at least five where the correct answer is a specific figure your finance or operations team already publishes.
Add adversarial and unanswerable questions. Include questions that are genuinely ambiguous across columns or intent, questions with no valid SQL given the schema, and questions that would require a table the user should not reach. Record the expected outcome for each: clarification, denial with reason, or a specific corrected answer.
Run cross-role permission tests. For each of three roles — a regional analyst, a manager, an administrator — ask the same question and record both the rows returned and the columns visible. Verify that the combined scope of multiple row-level rules matches the intended scope, and that a role lacking a masking-function privilege receives a NoPermission failure rather than unmasked data.
Score on validation outcome, not plausibility. A query that returns a believable figure while skipping a required join or widening the permitted row set fails the test even when the arithmetic looks right. Compare the system's allow, deny, warn, or repair decision against the expected decision you recorded in advance.
Log the misses and re-run. Every case the gate gets wrong becomes a permanent test. A pilot that ends with a stable, growing test set is worth more than one that ends with a demo.
FAQ
Does a better model remove the need for validation? No, because the failure is not primarily a modeling problem. A model can improve at translating a settled question into correct SQL; it cannot settle which of two revenue definitions your finance team means. Evidence on self-correction points the same way: in one 2026 preprint, a reflection round moved execution accuracy only from 0.451 to 0.468 while the model assigned confidence of at least 0.9 to 99% of its revised queries (What Predicts Correctness in Text-to-SQL?). Better generation raises the ceiling; validation is what catches the cases below it.
Does a semantic layer alone prevent data leaks? No. Knowing what a metric means and being permitted to see the underlying rows are separate guarantees. A pipeline with exact metric definitions but no access policy can still return rows the requester should not see, which is why row-level and column-level enforcement belong in the execution path rather than in the generated query.
How should I interpret a vendor's accuracy figure? Check what was measured, on what data, and under what conditions. Benchmark results on curated academic schemas and results on an organization's own warehouse are different regimes, and no source in this guide provides a controlled comparison of one system on both. Treat any published figure as a claim to reproduce in your pilot, not a planning assumption.
Is a prompt instruction ever enough? As a style guide, yes; as a control, no. Instructions shape how a model writes a query. They do not constrain what it can reach, and they degrade under adversarial or ambiguous input.
The First Step Is Defining What "Correct" Means
Every gate described above — intent resolution, metric binding, policy injection, database enforcement — depends on a definition someone wrote down. If "active customer" means three different things in three teams, no validation layer can decide which one a question meant, and the most sophisticated pipeline will faithfully apply the wrong contract.
The highest-value first move is therefore cheap and unglamorous: write down and version the definitions of your five most-contested business terms, with a named owner for each. Record the aggregation, the grain, the required filters, and the effective dates. That artifact is what a metric resolution layer binds to, what a validation gate compares against, and what an auditor reads when a number is questioned.
Singdata's governance and permission controls — row-level filtering applied to Agent-generated queries, column masking evaluated at runtime against user and role — are one platform that supports this discipline. They are not a substitute for it. A masking policy cannot tell you whether net revenue should exclude refunds, and a row filter cannot tell you which region a customer belongs to when two systems disagree.
The next concrete action: pick the term that has caused the most disagreement in the last quarter, assign an owner, and version its definition this week. Then build the pilot test set around it. That first definition is the one every downstream check will be measured against.
Previous posts
1. https://singdata.com/trending/natural-language-analytics-tools-permission-controls/
2. https://singdata.com/trending/vector-index-row-level-security-layout